English · 简体中文 · 繁體中文 · 日本語 · 한국어 · Türkçe · Русский · Tiếng Việt · ไทย · Deutsch · Español · Français · Українська · Polski · Português (Brasil) · العربية · فارسی · Bahasa Indonesia · Italiano · Ελληνικά · മലയാളം · Roman Urdu · Română

DSHRSI: Recursive Self-Improvement for DeepSeek Harness
Observe → Improve → Build on It → Again. A harness that keeps getting better at being yours.
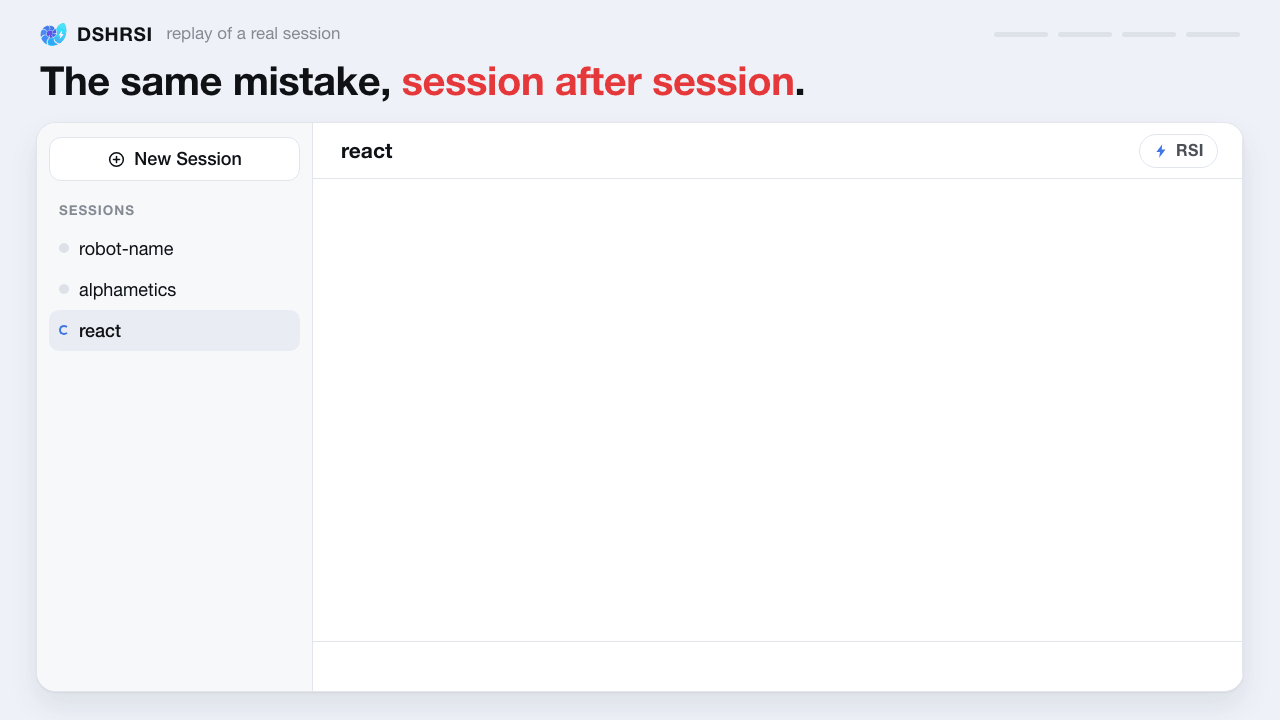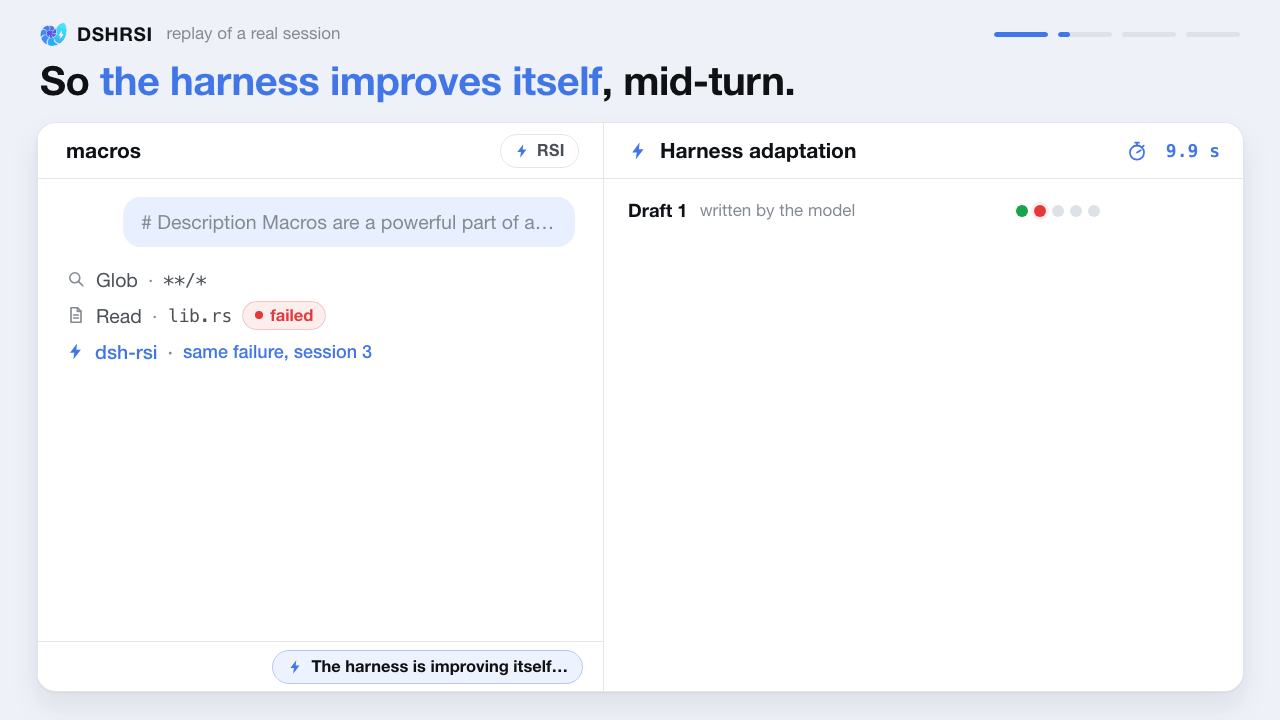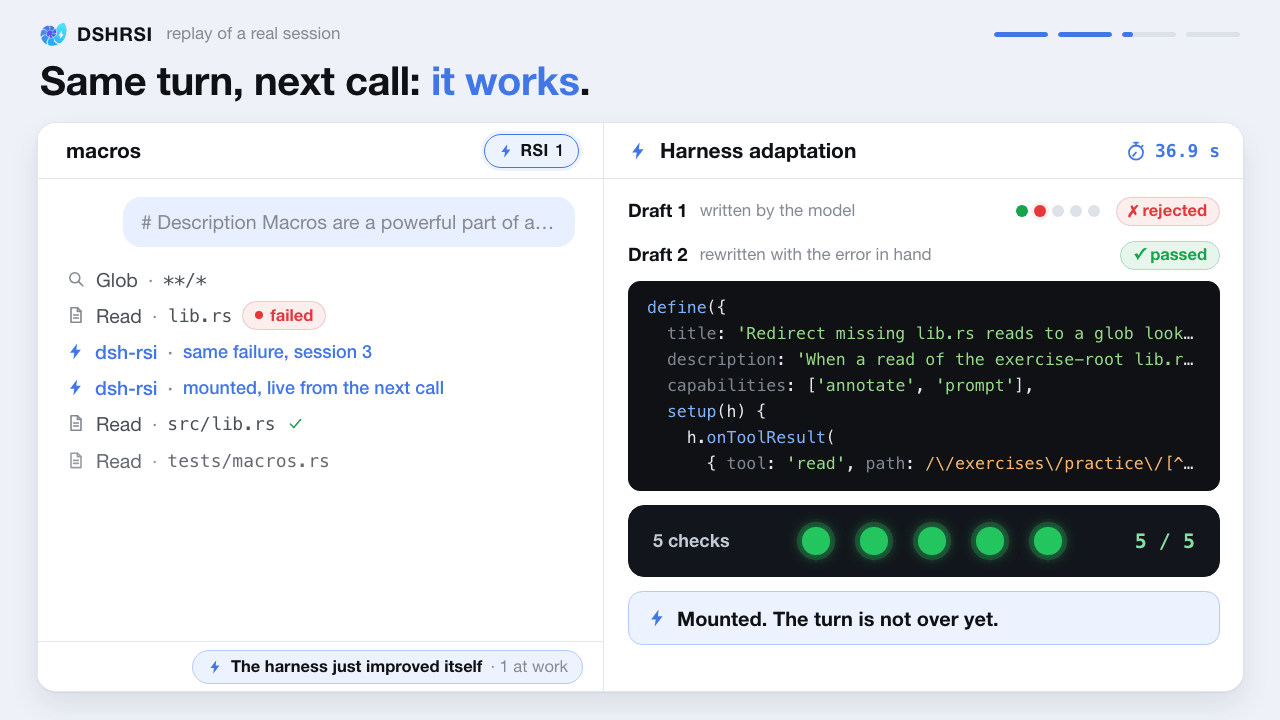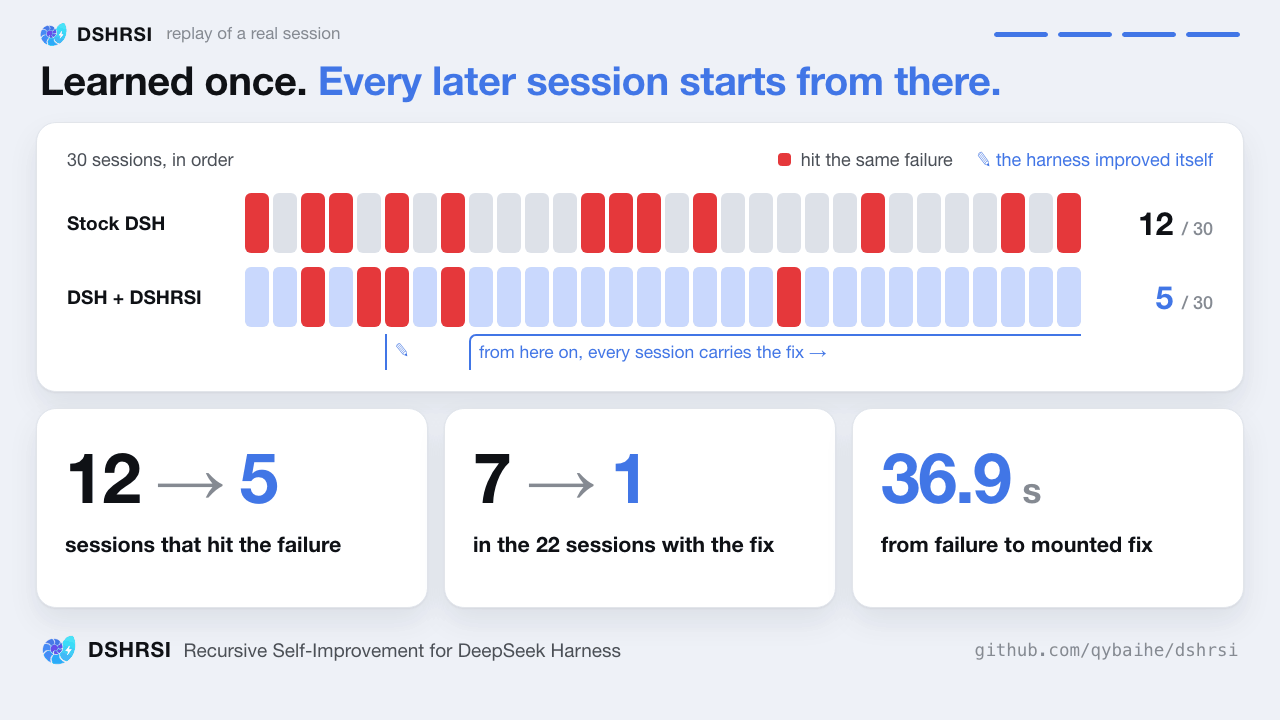
RSI means Recursive Self-Improvement, and DSHRSI is the open-source plugin that makes it real for DeepSeek Harness. The harness watches its own runs, has the session's own model write harness code for the trouble it finds, proves that code in a 5-stage gate, and mounts it before the turn is over. Then the improved harness runs the next session, and improves again. No fine-tuning. No pile of prompts. Code that is measured, kept, rewritten or thrown out.


🌐 Website · 📖 Plugin Reference · 🐛 Issues
What RSI Means · Quick Start · How It Works · Measured Results · Benchmarks · Detectors & Capabilities · Project Harness · Safety Defaults · FAQ
[!IMPORTANT] Developer Preview: DSHRSI is built against DeepSeek Harness
0.2.2-rc.3, which is itself a developer preview. There will be compatibility-breaking changes. An adaptation is code written by a model and run inside your harness. Its isolation guards against mistakes, not against malicious code. Read about the validation gate before you run it.
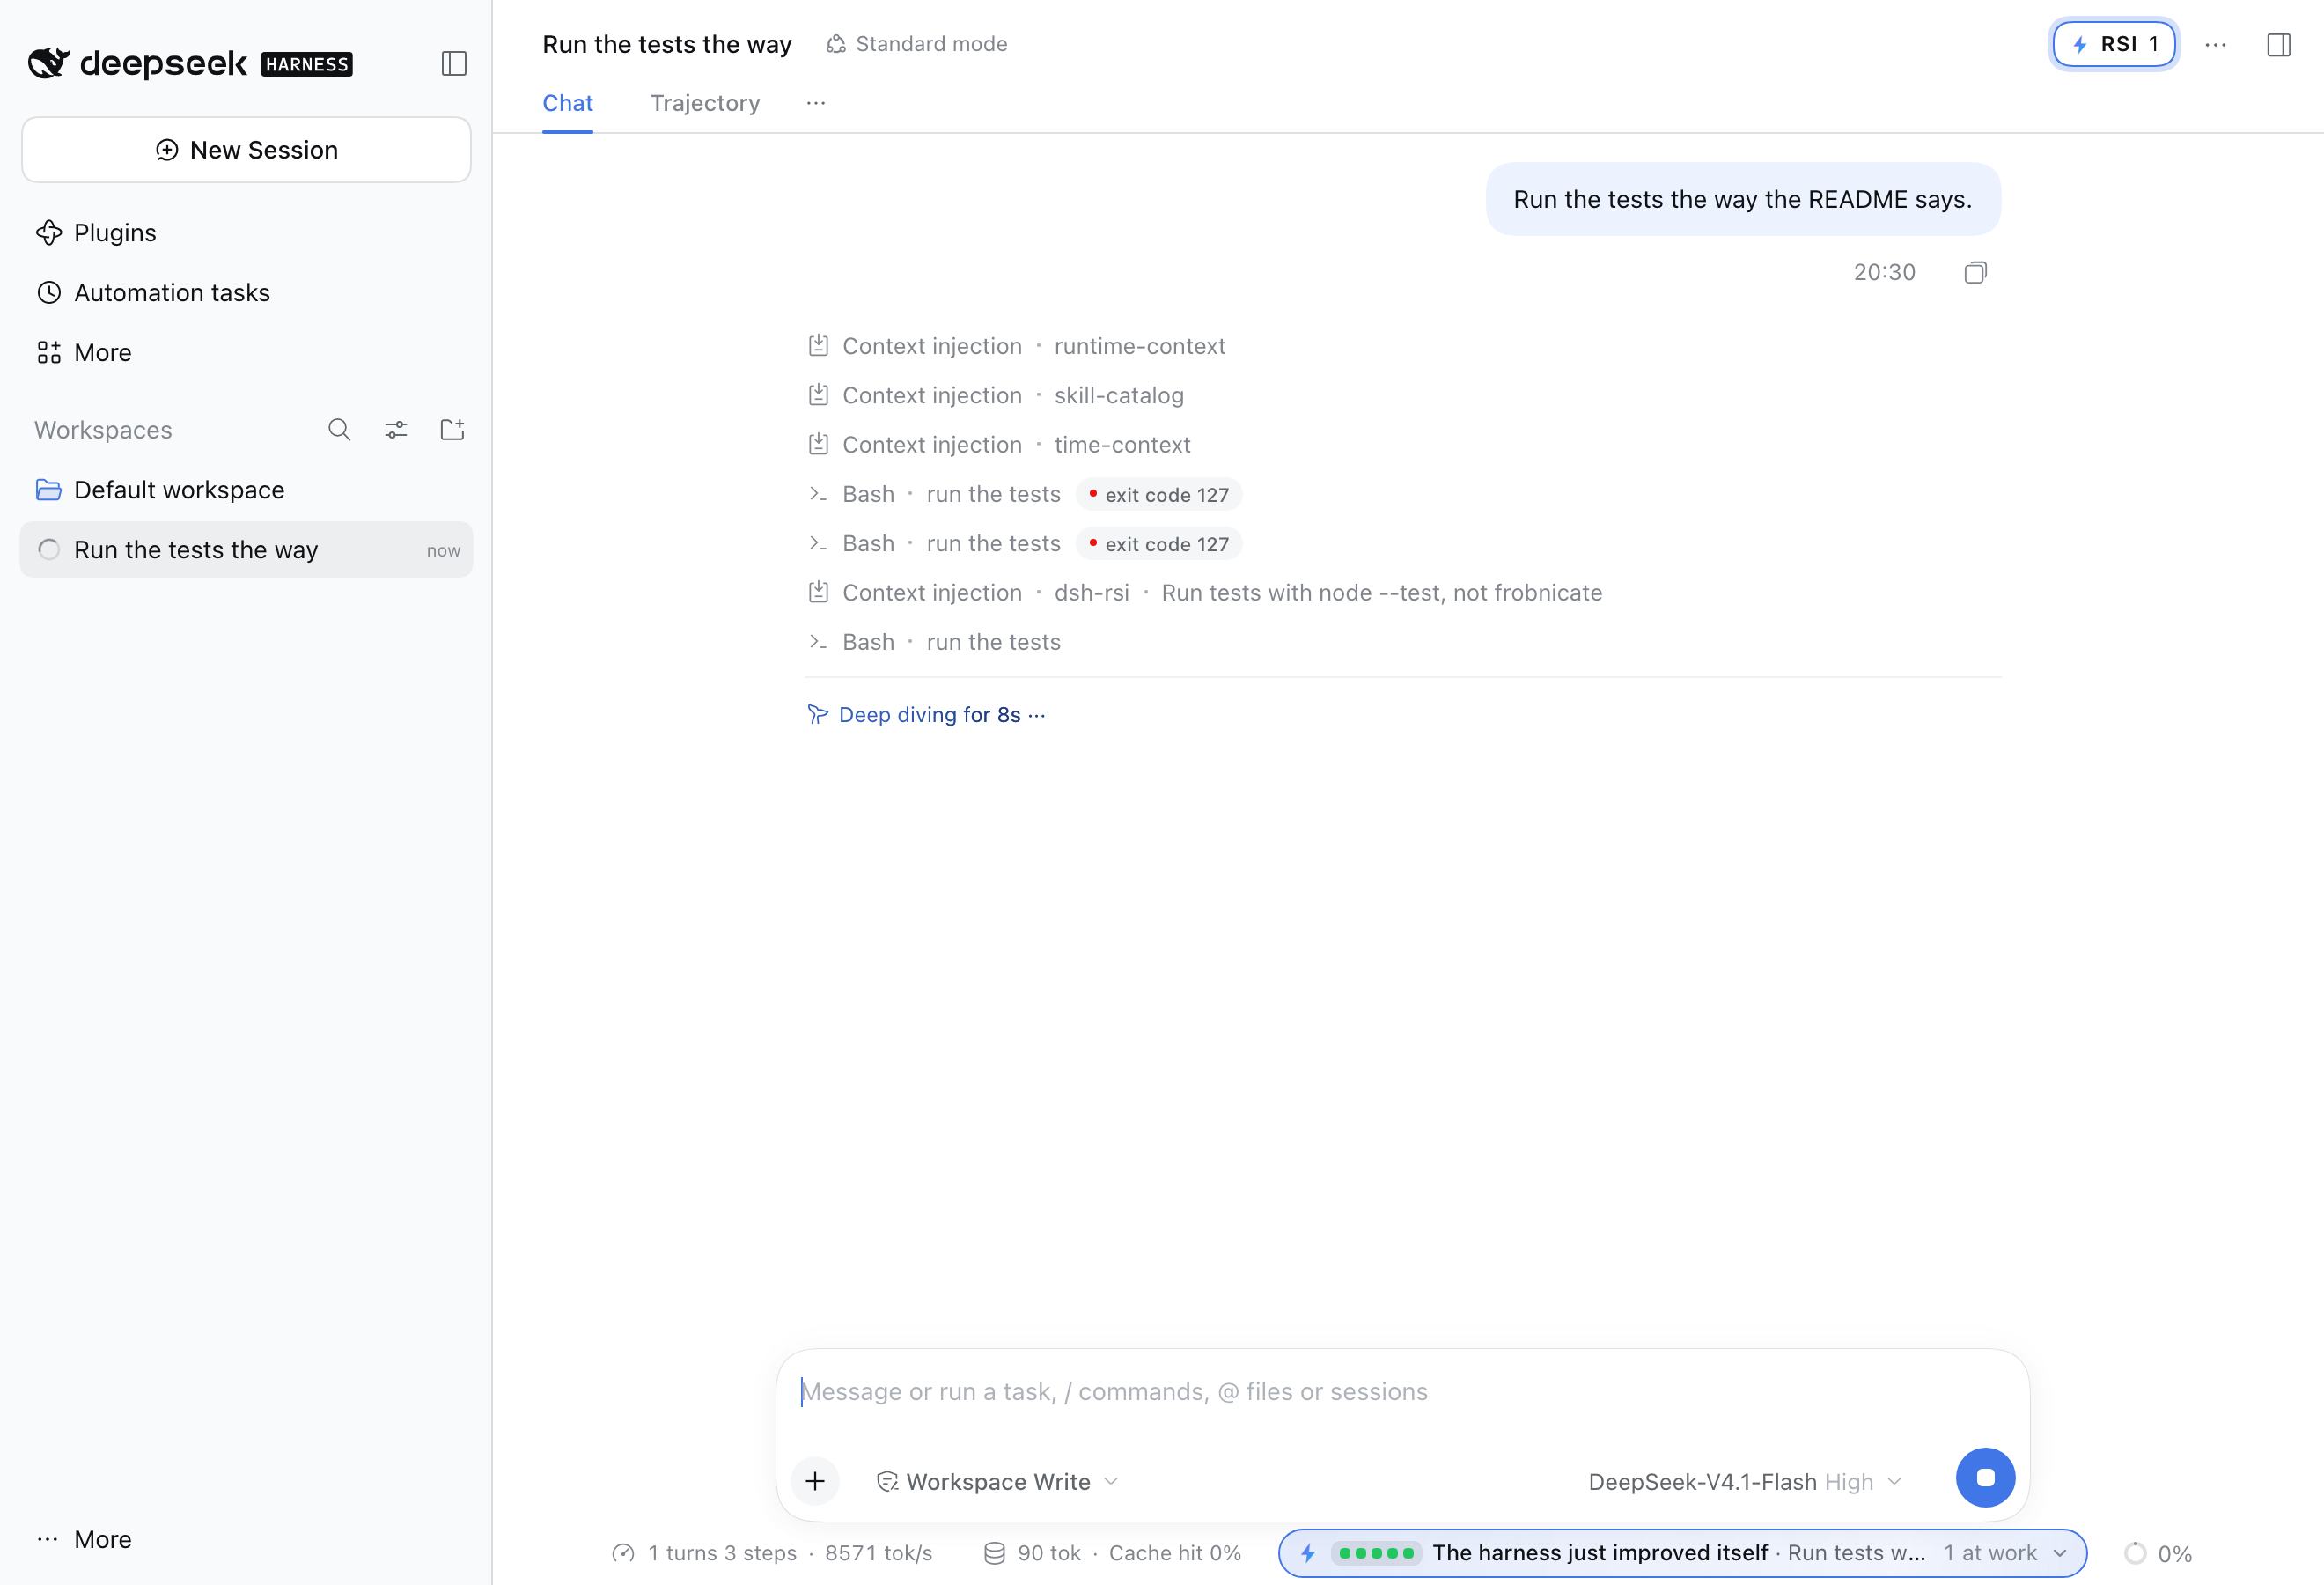
🔴 Without DSHRSIEvery session rediscovers the same facts: this machine has no |
🧬 With DSHRSIWhen the trouble comes back, the model writes a piece of harness code, it passes the gate, and it is live in that same turn. In 3 runs against a real model, 7 sessions out of 7 after the adaptation had no failed call. And the next improvement starts from there. |
🔒 Tighten-Only by DesignAn adaptation can add information, refuse a call, ask you first, or demand verification. No capability can allow what the harness would refuse. Rewriting results, adding tools and running commands wait for your approval. |
🔁 RSI = Recursive Self-Improvement
Not "rewrite itself". Recursive Self-Improvement: a system uses its own abilities to improve itself, and the improved system carries out the next round. Three words, and DSHRSI has to earn each one:
| What It Takes | How DSHRSI Does It | |
|---|---|---|
| Self | What acts and what is changed are the same system | The harness changes the harness. The adaptation is written by the model of the very session that hit the trouble. Nobody tunes it from outside |
| Improvement | "Better" has to be checkable | Every adaptation passes a 5-stage gate before it is mounted, and later sessions are held against it: what works is promoted, what throws is quarantined |
| Recursive | One round's output starts the next | The next session runs on the improved harness and is observed with it. An adaptation that did not hold is rewritten stricter from the evidence. One that is needed in a second workspace widens to the whole machine, and a project's rules travel to every teammate's harness |
Four loops, each inside the next: inside a turn → from session to session → the improvement itself gets improved → from a project to a machine to a team.
What is deliberately not recursive: the model's weights never change, and the detectors, the trigger policy and the validation gate are fixed code that no adaptation can touch. The part that modifies itself is checked by a part it cannot modify.
⚡ 30-Second Quick Start
1. Install It Where You Already Work
In the DeepSeek Harness desktop app or Web UI, open Plugins → Add plugin → Install a third-party plugin, paste the release package, select Install, then Enable now:
https://github.com/qybaihe/dshrsi/releases/download/v0.1.3/dsh-rsi-0.1.3.tgz
Or from the command line. Each profile keeps its own plugins, and dsh plugin add calls pnpm, which has to be on PATH:
dsh plugin --profile web add https://github.com/qybaihe/dshrsi/releases/download/v0.1.3/dsh-rsi-0.1.3.tgz
dsh web
2. Just Work
There is nothing to configure. DSHRSI stays out of sight until the same trouble comes back. Then the RSI badge lights up, the pill under the composer tells you the harness has just changed itself, and the next session starts already improved:
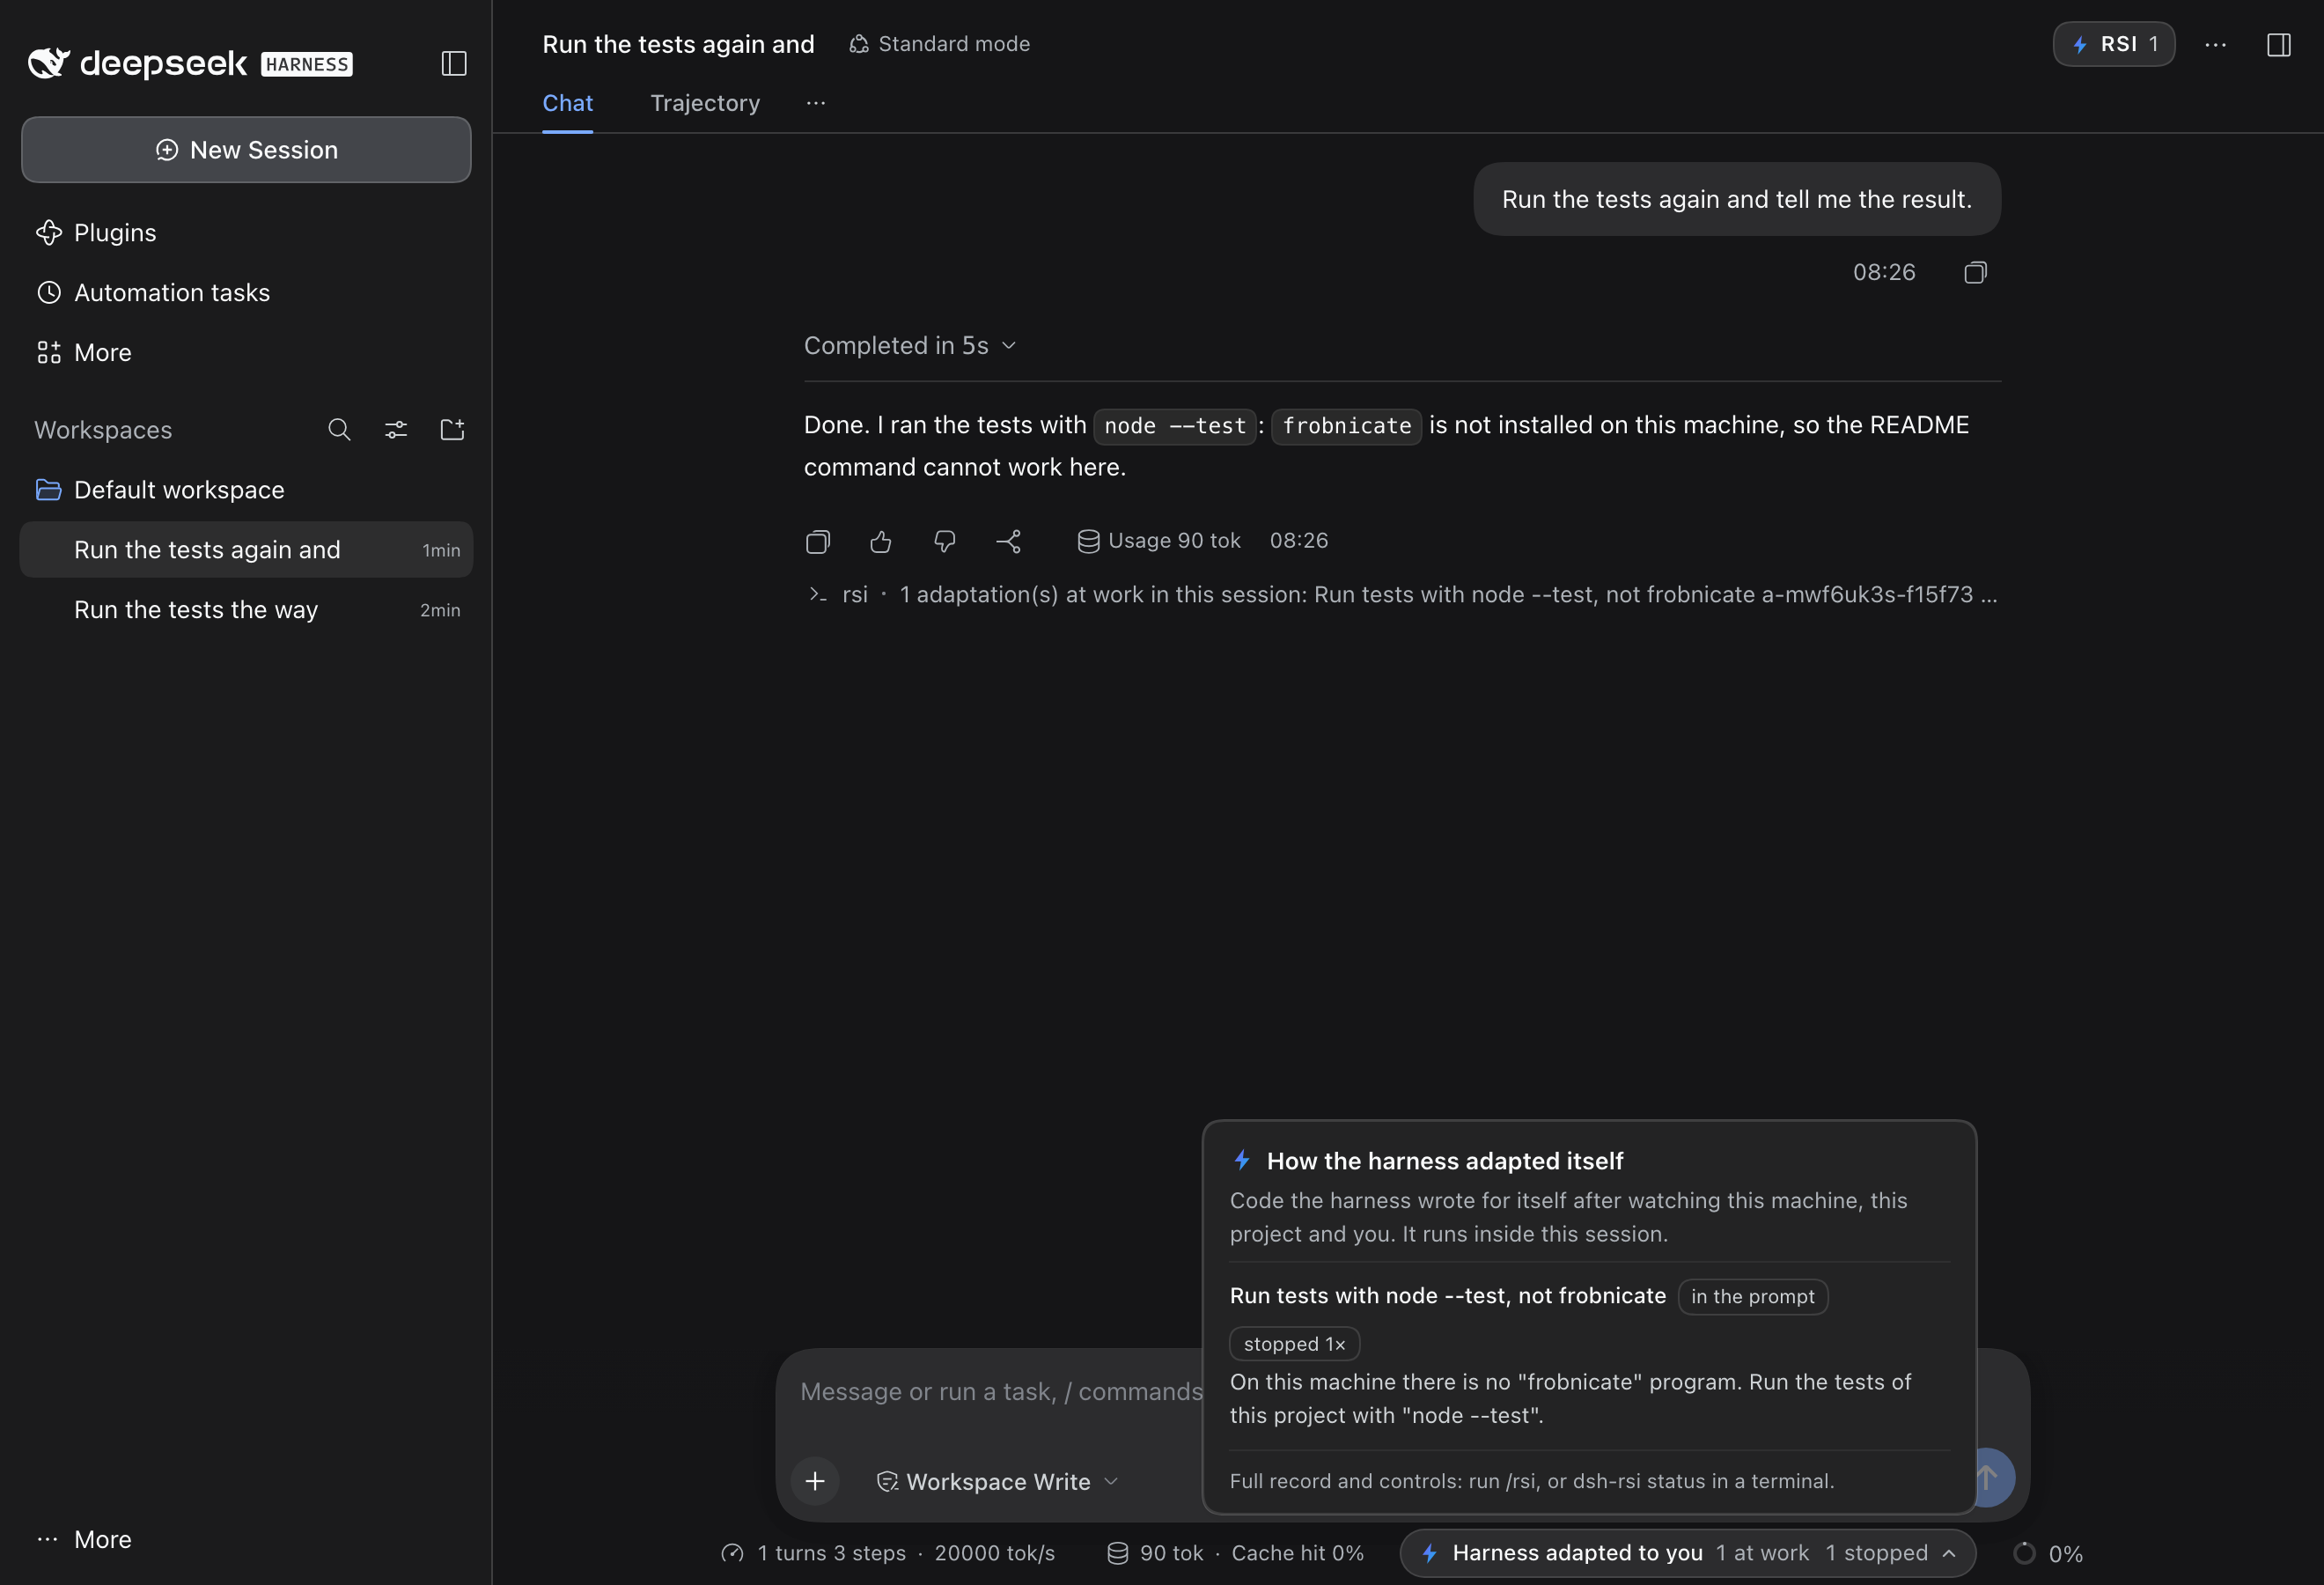
Type /rsi in any session to see what is mounted, which layer it belongs to, and what is waiting for your approval.
The desktop and headless profiles, plugin indexes, local tarballs and loading for a single run are covered in the plugin reference.
🧠 How DSHRSI Works: a Closed Loop Inside the Harness, Run Again and Again
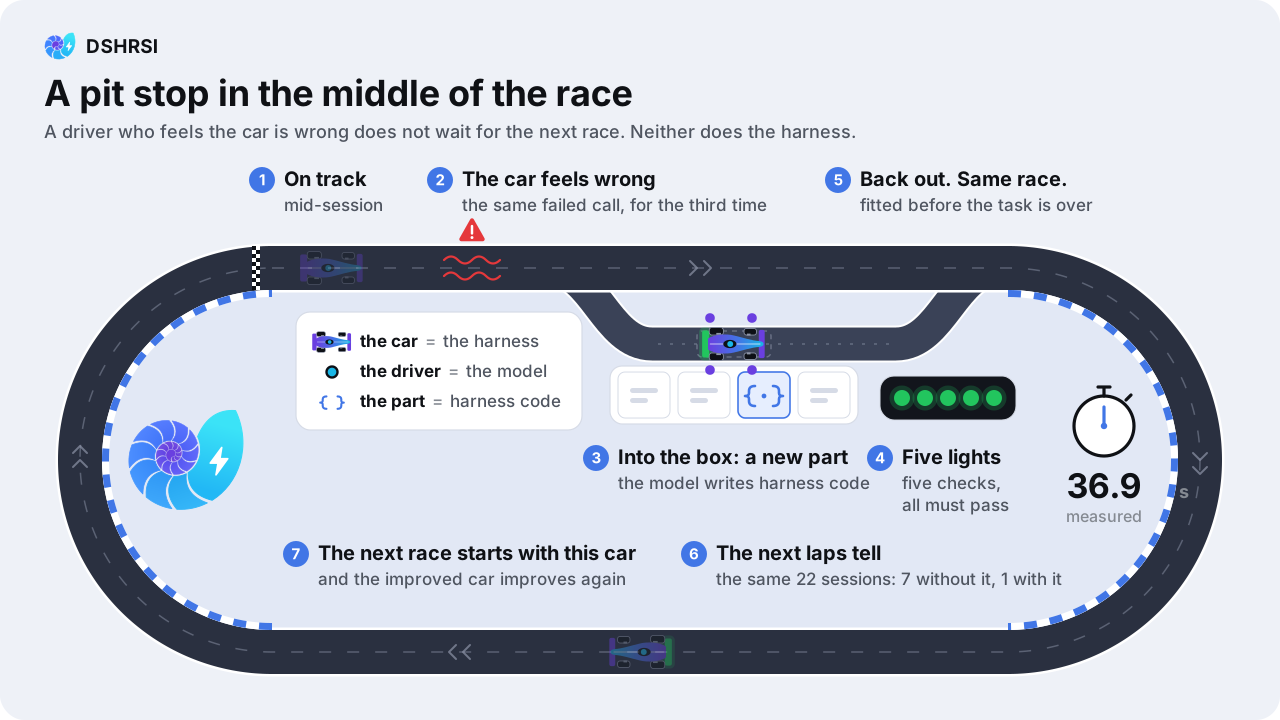
Skills, memory files and longer system prompts all work at the level of context: they add text and hope the model follows it. When it does not, the same failed call is made again in the next session.
DSHRSI works at the level of the harness. What it learns becomes code on the harness's own extension points:
| Stage | Mechanism | Effect |
|---|---|---|
| 1. Observe | 16 detectors read normalized session events: calls that fail again, causes of failure that keep coming back, flailing, user corrections, turns that end with nothing verified. | Trouble gets a signature that stays the same from one session to the next. |
| 2. Rewrite | The session's own model writes a JavaScript adaptation against a 10-capability API. Rejected code goes back with the reasons, twice at most, then a built-in template takes over. | The fix is harness code, not one more paragraph of prompt. |
| 3. Validate | Static → load → replay → regression → permission. The adaptation has to act on the calls that triggered it and must leave alone every call that succeeded in this session. | Code that does nothing, or that breaks what already worked, is never mounted. |
| 4. Mount | The adaptation runs in its own isolated context, with timeouts on every call, and takes effect before the next model request. | The turn that hit the trouble is the first to benefit. |
| 5. Keep and Share | Each machine keeps a library of adaptations. What works is promoted, what throws is quarantined, what did not hold is rewritten stricter, and project rules are written into the repository. | The next session starts adapted, and teammates get the project's rules once they accept them. |
| ↻ Again | The next session runs on the harness that stage 5 left behind, and stage 1 observes it with every adaptation in place. | Improvement is built on improvement. That is the recursion. |
🔬 Measured Against a Real Model
These numbers come from running a real model, mimo-v2.6-pro, through real dsh sessions (npm run test:live). Nothing in this table is simulated.
How to read this: the sample is small. One model, three scenarios, a handful of sessions each. It shows that the loop works end to end. It is not a statistical statement about success rates, and nothing got faster: writing an adaptation waits 30–60 seconds for the model. The larger runs are in Benchmarks.
| Scenario | Without DSHRSI | With DSHRSI | What the Harness Wrote |
|---|---|---|---|
Missing command: the instructions say python, the machine only has python3 |
❌ 5 / 5 sessions made the failed call | ✅ 0 / 7 sessions after the adaptation (9 / 9 before it) | deny + prompt, written by the model, passed the gate on the first attempt |
| A rule the user stated once: never modify one file, write to a draft of it instead | ❌ The next session edited the file | ✅ The next session wrote to the draft, unprompted | deny + prompt, written by the model right after the correction |
| A fix nobody asked to verify | not run | ⚪ Nothing written: the model verified its fix in 3 / 3 sessions, so there was nothing to learn | none |
📊 Benchmarks: Four Suites, Two Models, Task by Task
Stock DeepSeek Harness against DeepSeek Harness + DSHRSI, in 3,390 real dsh sessions: the same model, the same prompts, the same sandbox, the same tasks. The plugin runs at its default settings and starts every suite with an empty library. Tasks solved on the three suites that ran to the end:
| Benchmark | Tasks | mimo-v2.6-pro Stock |
mimo-v2.6-pro + DSHRSI |
mimo-v2.6-flash Stock |
mimo-v2.6-flash + DSHRSI |
|---|---|---|---|---|---|
| Aider Polyglot, first try | 225 | 224 (99.6%) | 224 (99.6%) | 220 (97.8%) | 223 (99.1%) |
| Aider Polyglot, within two tries | 225 | 225 (100.0%) | 225 (100.0%) | 225 (100.0%) | 225 (100.0%) |
| HumanEval | 164 | 163 (99.4%) | 162 (98.8%) | 162 (98.8%) | 162 (98.8%) |
| HumanEval+ | 164 | 156 (95.1%) | 157 (95.7%) | 153 (93.3%) | 153 (93.3%) |
| MBPP | 378 | 374 (98.9%) | 371 (98.1%) | 368 (97.4%) | 369 (97.6%) |
| MBPP+ | 378 | 320 (84.7%) | 319 (84.4%) | 308 (81.5%) | 315 (83.3%) |
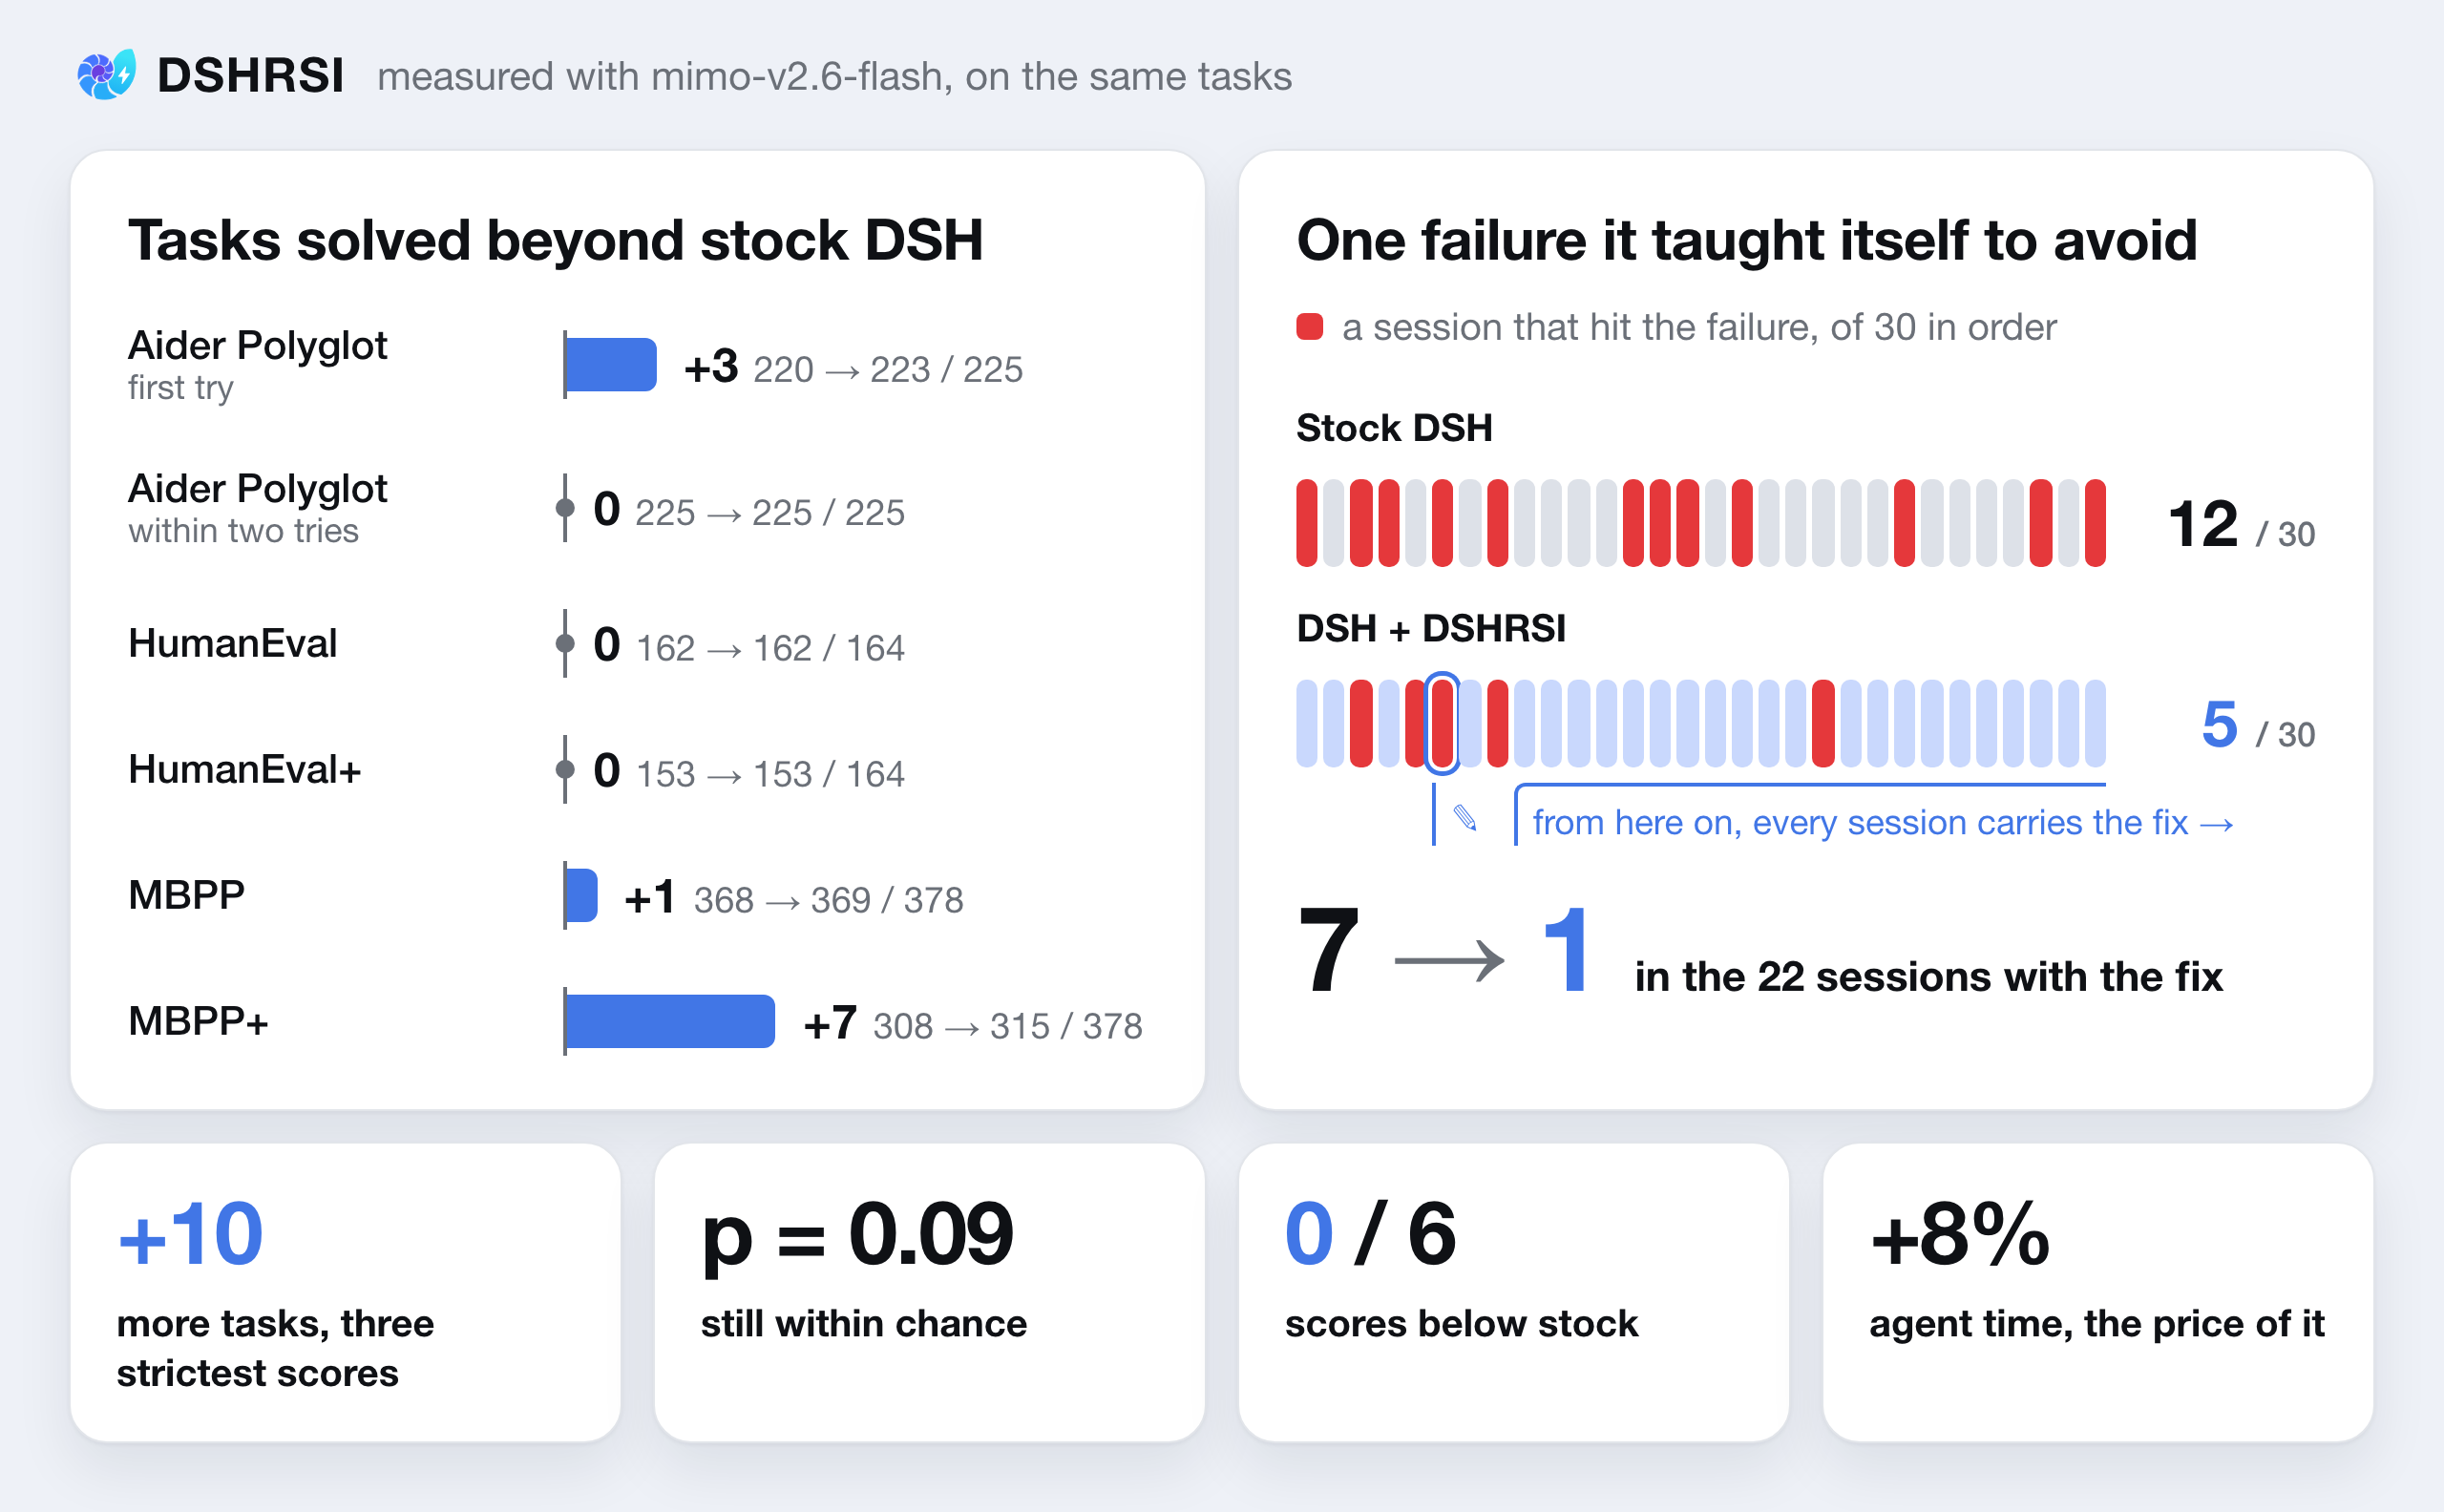
How to read this: on tasks solved, the two harnesses cannot be told apart. The largest gain is +7 (MBPP+ with
mimo-v2.6-flash), the largest loss is −3 (MBPP withmimo-v2.6-pro), and no difference holds up in an exact McNemar test on the same tasks (smallest p = 0.17). When the agent can run its own code, these suites are close to their ceiling for both models, and every task is a fresh, clean directory: very little comes back for a harness to learn from.
What DSHRSI did do, without a single hint, was change itself. Across the eight runs the models wrote 56 adaptations; 15 of them acted, and 10 of those had been widened to the whole machine. For each of the 10 we took the tasks that started after it and compared them with the very same tasks under stock DSH:
| Failure the Harness Taught Itself to Avoid | Stock DSH | DSH + DSHRSI | p |
|---|---|---|---|
A test run that dies on its first failed assertion (MBPP, mimo-v2.6-pro) |
16 of 310 tasks | 3 of 310 | 0.002 |
Reading a file at a path that does not exist (Polyglot, mimo-v2.6-flash) |
7 of 151 tasks | 1 of 151 | 0.07 |
| The other 8 adaptations | no measurable change |
Neither of the two made more tasks pass, and the plugin cost about 8–9% more agent time and input tokens. All ten are listed in the benchmark notes.
LiveCodeBench v6 was cut short: the model account ran out of balance part-way through. On the tasks both sides had finished by then, stock DSH solved 94 and DSHRSI 96 of 105 with mimo-v2.6-pro, and 42 against 42 of 51 with mimo-v2.6-flash. For the same reason the second pass, the same tasks again on the library the first pass left behind, has not been run yet.
The protocol, the cost and failure tables, the limits and the commands to reproduce all of it are in the benchmark notes.
🛡️ Detectors & Capabilities
16 detectors decide when the harness should change. The full list is in the plugin reference.
10 capabilities are everything an adaptation can do. It reaches the harness only through them:
| Capability | What It Does | Tier |
|---|---|---|
annotate |
Appends a note to a tool result | ✅ automatic |
steer |
Adds a note before the next model request | ✅ automatic |
deny |
Refuses a tool call and gives the reason | ✅ automatic |
ask |
Requires the user's approval for a call | ✅ automatic |
block |
Turns a tool result into an error that carries a correction | ✅ automatic |
verify |
Keeps the turn from ending while a condition is not met | ✅ automatic |
prompt |
Adds a standing section to the system prompt | ✅ automatic |
rewrite |
Replaces the text of a tool result | 🔐 needs approval |
tool |
Registers a new tool for the model | 🔐 needs approval |
exec |
Runs a command through the harness's shell tool, under the same sandbox and approval rules | 🔐 needs approval |
This is the adaptation the model wrote in the first scenario above:
define({
  title: 'Route python invocations to python3',
  description: '...',
  capabilities: ['deny', 'prompt'],
  setup(h) {
    h.promptSection('On this machine there is no `python` executable; use `python3`.')
    h.beforeTool({ tool: 'bash', command: /(^|[;&|(]\s*)python(\s|$)/ },
      () => h.deny('`python` is not installed on this machine. Use `python3` instead.'))
  },
})
🧩 Three Layers, and a Harness per Project
Every adaptation belongs to one of three layers. Each layer can be switched off on its own:
| Layer | What It Holds | Example | Where It Applies |
|---|---|---|---|
machine |
Facts about this computer | No python; a port is taken; an internal host does not resolve |
The workspace where it was learned, then the whole machine once a second workspace hits it |
user |
How you want to be treated | A reply marked as bad with the reason "too long" | The whole machine |
project |
The rules and habits of one repository | "This repository uses pnpm, always" | The workspace, and the repository itself: the rules are committed with the code |
The project layer travels with the code:
- Commit to share, delete to unplug. One file is one adaptation.
- Nothing runs because it was cloned. Each machine accepts the exact content of the files with
dsh-rsi trust, and accepts them again when they change. - A project can only make the harness more conservative, never less. Settings such as
autonomyare out of a project's reach. - Portable beyond a repository.
dsh-rsi exportanddsh-rsi importcarry the machine and user layers to another computer as one file.
🔒 Safety & Configuration Defaults
- Tighten-Only Automatic Tier — Without your approval, an adaptation can only add information, refuse, ask, or demand verification. Its
denyandaskcan only make the verdict of the other policies stricter. - Approval for Power (
autonomy: tighten) — Adaptations that rewrite results, add tools or run commands are stored asproposedand wait fordsh-rsi approve <id>. - Invisible Until Needed — With no friction and nothing mounted, the system prompt, the tool list and the messages are unchanged byte for byte. An end-to-end test guards this.
- Contained Failures — A handler that throws never affects the tool call it is attached to. After three errors the adaptation is quarantined.
- Everything on Record — Every decision, friction, mount and action is logged.
dsh-rsi disable,retireandrollbacktake an adaptation out or back. - Three Modes —
adaptmounts directly (the default),proposegenerates and waits for you,observeonly records.
❓ FAQ
Does DSHRSI fine-tune or change the model?No. The model's weights are untouched and nothing is trained. What changes is the harness: the code that runs around the model's prompts and tool calls. RSI here is Recursive Self-Improvement at the level of the harness: it improves itself from its own runs, and every round starts from the harness the last round left behind.
Is this really "recursive", or just a harness that learns rules?The recursion is concrete and it is in the code. A new session mounts everything the library holds, so the detectors observe a harness that has already changed. When the same trouble occurs twice in sessions that had an adaptation mounted, the model gets the current source and the evidence, and writes a stricter version; the old one is kept for rollback. Trouble met in a second workspace widens an adaptation to the whole machine. What does not recurse is the judge: detectors, trigger policy and validation gate cannot be changed by any adaptation.
How is this different from skills, memory files or a longer system prompt?Those add text that the model may or may not follow. An adaptation is code on the harness's extension points: it can refuse a tool call before it runs, require your approval, or keep a turn from ending while nothing was verified. In the measured runs, the model still tried python in 3 sessions after being told not to, and the call was refused before it ran.
Writing an adaptation waits for one full model response: 30–60 seconds on mimo-v2.6-pro, during which the step stands still. Mounted adaptations run in-process with timeouts. No speedup was measured and none is claimed.
The automatic tier cannot allow anything the harness would refuse, and the powerful capabilities wait for your approval. The code runs in its own node:vm context behind a JSON bridge. This guards against mistakes and casual misuse. It is not a security boundary against malicious code, so read a project's .dsh-rsi/ files before you run dsh-rsi trust.
Adaptations are written by the session's current model, or by the one you set with provider and model. If the model cannot produce code that passes the gate, built-in templates take over. Runs so far used two models of one family, mimo-v2.6-pro and mimo-v2.6-flash.
It ships as an ordinary third-party plugin with the metadata the plugin pages read, and it installs into the web profile the app wraps. It has not been verified inside the real desktop app yet.
It can always be taken back: the harness's own code is never touched, and no version of an adaptation is ever deleted. The harness backs out by itself when an adaptation keeps failing, or when a call it refused turns out to work. You can do it too: /rsi undo takes back the last change, dsh-rsi restore puts the whole harness back to an earlier point, and /rsi off runs the stock harness. All of this takes effect in the session that is already running. How going back works.
/rsi in a session, or dsh-rsi status in a terminal. dsh-rsi show <id> prints an adaptation's source and validation report; disable, retire and rollback take it out or back. Set mode: observe to record without changing anything.
📚 Documentation & Links
- 📖 Plugin Reference — every detector, capability, command and setting
- 🚀 Installation Sources & Profiles
- 🧩 Layers & the Project Harness
- 🔬 The Validation Gate
- 🛠️
dsh-rsiCommand Line · ⚙️ Configuration - ⚠️ Known Limits
- 📊 Benchmark Protocol & Results
- 🧱 DeepSeek Harness — the harness this plugs into
🤝 Contributing & Community
Issues and PRs are welcome at qybaihe/dshrsi. Before submitting a PR:
npm install && npm test # 130 unit tests, then 29 end-to-end tests; no key needed
The end-to-end tests replace the model endpoint with a simulated one. Everything else is real: the dsh process, tool execution, the session log and plugin installation.
📄 License
Created in T3 Code.
No comments yet. Be the first to write one.