dsh-chat-cost
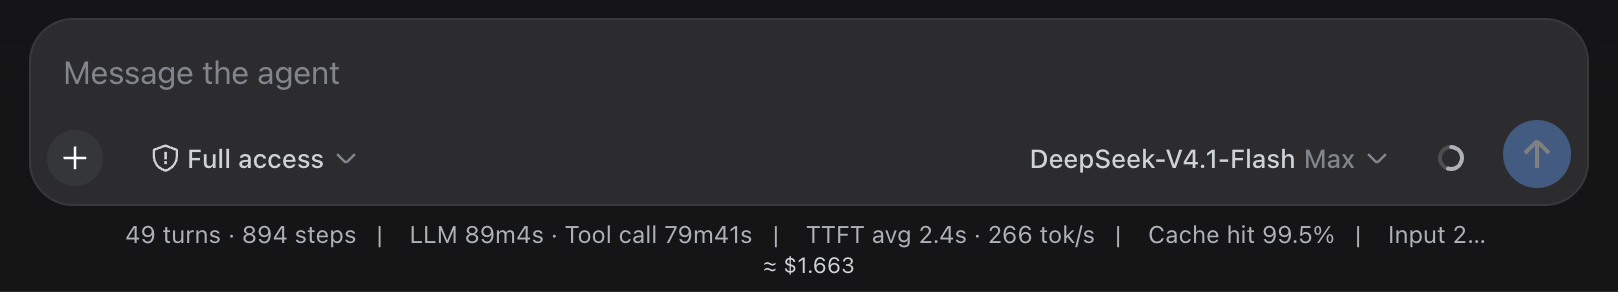
Live token cost for every chat in the DeepSeek Harness (dsh) Web UI: the chat itself, its subagents and the whole session tree, priced from a bundled multi-provider catalog, with an append-only JSONL cost log written into your project folder.



Keywords: DeepSeek Harness plugin, dsh plugin, dsh-plugin, token cost, cost per chat, subagent cost, session tree cost, LLM spend tracking, token usage, cost log, JSONL, local-first, DeepSeek V4.1 Flash, DeepSeek V4 Pro, OpenAI GPT-5, Anthropic Claude, Google Gemini, Kimi K3 (Moonshot), xAI Grok, Mistral, cache read and cache write pricing, peak and off-peak pricing, Cordis plugin.
Status
Working end to end, and verified against a running host rather than only in tests: the bundled seven-provider catalog, the pricing engine (peak tiers, cache read and write rules), the Host half that walks the session tree, prices every session per interval and appends the JSONL cost log, per-turn pricing folded from the session's own events, the six budget tools (cost_price, cost_history, cost_estimate, cost_plan, cost_mark, cost_scenarios), and the client readout in English, Chinese and Russian — in the composer for the chat, and under every finished answer for that answer.
Known limits, stated rather than hidden: only live sessions expose provider usage, so a persisted-only subagent session is listed without a price; a chat known only from the log has no turn boundaries, so it shows a total and no per-answer badges; long-context tier prices published for some Gemini and Grok models are not applied yet.
Configuration
- id: dsh-chat-cost
  name: dsh-chat-cost
  config:
    writeLog: true        # append the JSONL cost log into the project folder
    logDir: .dsh-cost      # directory name inside the project folder
    language: en          # en | zh | ru; omit to follow the harness locale, then the browser
    ledgerTailBytes: 2097152  # how much of the cost log is read back per summary (2 MiB)
Features
- Multi-provider prices. A bundled snapshot of the models.dev catalog covers seven providers — DeepSeek, Moonshot, OpenAI, Anthropic, Google, xAI, Mistral — and every priced model of each (139 models today).
- Honest arithmetic. DeepSeek is priced from its own published table including peak and off-peak tiers; cache writes bill at each provider's own cache-write price where one exists (Anthropic, OpenAI) and at the input price otherwise; a model with no price shows
—rather than an invented number. - Breakdown by chat, subagents and session tree. The hover tooltip separates this chat from its subagents and shows the tree total, the token buckets and the models involved.
- Cost log in the project folder.
<project>/.dsh-cost/cost.jsonl, one JSON object per session per flush, with the tree position, four token buckets, cumulative and delta cost, and the pricing source. Inside a git work tree,.dsh-cost/is added to the project.gitignoreon first write; a plain folder is left untouched — the log is welcome there, clutter is not. - Interval pricing. The JSONL log is the base: every flush prices only the tokens that arrived since the previous record, at the tariff in effect at that moment, so a chat that crosses a DeepSeek peak boundary keeps the price it was really billed at instead of being re-priced retroactively.
- Bounded, cached reads. A summary reads only the tail of the log (
ledgerTailBytes, 2 MiB by default) and reuses the cached read while the file's size and mtime are unchanged; when the tail starts mid-file the plugin reportstruncatedandskippedBytesinstead of pretending to know the whole history. - Nothing is quietly unaccounted. Spend that belongs to no plan unit is named in the tooltip (
$1.230 is not attributed to any plan unit) rather than folded into a total. - The price of each answer, under the answer. Every finished turn gets its own cost in the transcript, priced from that turn's own usage events rather than sliced out of the session total, and refreshed the moment the turn closes. The composer readout shares one poll with those badges, so a finished answer updates both at once.
- Every chat, open or not. A chat that is not currently open has no live session, so the readout prices it from the cost log and labels the number as recorded; a chat the log has never seen shows
—with the reason instead of disappearing. Opening it makes it live, prices it exactly, and writes the missing record. - Three languages. English, Chinese and Russian, chosen from the plugin config, then the harness locale, then the browser language.
Install
dsh plugin --profile web add dsh-chat-cost
The package is a DSH bundle: the profile reconciles its patch layer automatically (a dependency declaring dsh.bundle joins dsh.profile.bundles), so no patch editing is needed. Restart the host afterwards.
Pricing rules
| Rule | Behaviour |
|---|---|
| DeepSeek | official table, peak hours 01:00-04:00 and 06:00-10:00 UTC on weekdays double the price; cache writes have no separate fee, so they bill at the input price |
| Other providers | bundled models.dev snapshot, cache read and cache write prices used exactly as published |
| Unpublished cache read | falls back to the input price, which is an upper bound |
| Unknown model | resolves to no price; the readout says — and the tooltip names the model |
| Attribution | the log is the base: a recorded interval keeps the price it was billed at, only new tokens are priced |
data/prices.json records where it came from (source) and when it was taken (generatedAt), so the age of a price is checkable rather than assumed. Refresh it with npm run prices (the seven curated providers) or npm run prices:all (every provider in the catalog).
How the number is computed
The summary is built ledger-first: recorded deltas are summed from the log file, and only the tokens that arrived after the last record are priced at the current tariff. A chat that spans a peak boundary therefore shows what it really cost, not a retroactive double.
Cost log format
{"ts":"2026-09-12T20:00:00.000Z","plugin":"dsh-chat-cost@0.6.8","rootSessionId":"root-1","sessionId":"child-1","parentSessionId":"root-1","depth":1,"kind":"subagent","provider":"moonshot","model":"kimi-k3","pricingSource":"catalog","tier":"flat","tokens":{"uncachedInput":5000,"cacheRead":0,"cacheWrite":0,"output":1000},"totalTokens":6000,"deltaTokens":{"uncachedInput":1000,"cacheRead":0,"cacheWrite":0,"output":200},"deltaTotalTokens":1200,"cumulativeUsd":0.014,"deltaUsd":0.002}
What it writes
Everything lives in the project folder, next to the work it describes.
| Path | Written by | What it holds |
|---|---|---|
<project>/.dsh-cost/cost.jsonl |
every flush | one JSON object per session per interval: tree position, four token buckets, delta and cumulative cost, and the tariff it was billed at |
<project>/.dsh-cost/plan.json |
cost_plan, cost_scenarios |
the priced work plan: units, chosen routes, what did not fit, the routing comparison |
<project>/.dsh-cost/budget.json |
cost_plan {action: budget} |
the money limit and its note |
<project>/.dsh-cost/plan.md |
cost_plan |
the same plan as a document for a human, in the language the readout reports |
The log is append-only: a record is never rewritten, which is what makes interval pricing possible. Remove the folder and the plugin starts from nothing — it keeps no state anywhere else.
Privacy
No account, no telemetry, no server. At runtime the plugin makes no outbound request at all: prices come from the bundled snapshot, the widget asks only the local host route, and the log is written into your own project folder. The one command that touches the network is npm run prices, which rebuilds the catalog from models.dev and is meant for a maintainer before a release, not for a user.
Releasing
npm test            # 142 tests; the schema checks need a DSH profile for the validator
npm run prices      # refresh the bundled catalog before a release
npm version minor
npm publish --access public
for f in README.md README.zh.md README.ru.md; do echo "$f: $(git hash-object $f)"; done
Prose check (optional, for maintainers)
The three READMEs are written by an assistant, so two failures are possible that no unit test sees: invisible characters and paste leftovers, and facts that change while a paragraph is rewritten. humanizer-ru covers both, with published false-positive measurements, and scripts/prose-check.mjs wraps it:
uv tool install humanizer-ru
npm run prose            # artefacts (a hard gate), facts against the last release, soft style signs
npm run prose -- --strict  # also fail when the tool is absent, for CI
Class A artefacts fail the run; class B markers (invisible characters and exotic spaces, whose false-positive rate the tool measures as small but not zero) are printed to look at and never fail it. A lost term from scripts/prose-terms.txt (package name, log path, tool names, the two client slots) fails too; every other lost number or quotation is printed for a human to judge, because a version bump legitimately changes numbers. Soft style signs are printed and never fatal — the tool itself refuses to call them evidence, and a counter should not decide prose. It is not part of npm test: the suite must run for anyone who installs the package, and a Python tool is not a dependency of a Node plugin.
A release can also run through the publish workflow (Actions → publish → Run workflow): it tests, refuses a version that is already on the registry, and publishes with --provenance through npm trusted publishing, so no npm token is needed. The one-time trusted-publisher setup is written at the top of the workflow file.
The package is a DSH bundle: dsh plugin --profile web add dsh-chat-cost installs it and the profile reconciles the patch layer by itself, so a release changes nothing for a user who already has it except the version. Bump PLUGIN_VERSION in lib/index.js together with the package version — it stamps every cost-log record, which is how a ledger entry can be traced back to the release that wrote it. After editing any README, re-record the hashes in README.i18n.yaml: a test fails until the three languages agree again.
Tests
npm test
Covers the pricing engine (route mapping, id canonicalization, peak windows, cache rules, unknown models), the per-turn fold (a streamed sample replaced by the final one, steps summed within a turn, the model in effect attributed to the turn that used it), the usage reader against every shape the harness hands over (flat, the projection's totals wrapper, a single step, the cache envelope), the context discipline of both halves (Cordis throws on any property a plugin did not inject, which took the host down once and the web shell once, so the source is checked mechanically), the log records and file writes against real files in a temporary directory, the plugin activation path (apply against a stub host: route, six tools, turn-driven flush, disposal), overlapping flushes, and the shipped client bundle rendered with a React-like hook store — asserting that all three languages define the same keys, that every message renders with its arguments, and that language resolution follows config → harness locale → browser.
Two suites go further than a plain checkout can: the schema checks run the tool schemas through the harness's own validator, and the boot suite loads the plugin on the real Cordis the harness uses (where reading config from the context instead of the loader argument throws). Both need packages that resolve only inside a DSH profile, so outside one they are reported as skipped rather than silently passing. A third check is not a suite at all: the published tarball is verified by running the same suite inside it, unpacked. For the full run:
dsh plugin --profile web add link:$PWD
npm pack && tar xzf dsh-chat-cost-*.tgz -C ~/.dsh/profiles/web/pack-check \
  && (cd ~/.dsh/profiles/web/pack-check/package && npm test)
Budget planning
The plugin turns the cost log into a constraint: the model plans the work, the plugin prices it, packs it under a money limit and records what actually happened.
| Tool | Purpose |
|---|---|
cost_price |
prices and cache rates for a provider or model, so a route is chosen deliberately |
cost_history |
actual spend per marked unit and per model, with P50/P90 spread — the calibration source |
cost_estimate |
prices a list of units, packs them under a budget, and reports what would not fit |
cost_plan |
writes or reads <project>/.dsh-cost/plan.json (plus a generated plan.md), and sets the money budget |
cost_mark |
opens a plan unit, so later spend is attributed to the plan instead of guessed from timestamps |
cost_scenarios |
compares routings — quality, connected, economy, balanced — and names the models worth connecting for this project |
cost_plan   {action: write, budgetUsd: 20, units: [...]}   -> plan.json + plan.md, 20% held back for rework
cost_mark   {label: research}                              -> spend from here belongs to `research`
cost_history {}                                            -> research: $1.84 actual against $2.10 expected
cost_plan   {action: budget, budgetUsd: 25}                -> the widget then shows "≈ $0.42 / $25.00"
Two rules make the estimates usable rather than decorative. Estimates are ranges: a unit priced from declared tokens is exact, anything else carries a P50 and a P90 (twice the expected work by default, and the tool says whether the number came from declared tokens, from history, or from a bootstrap default). And a budget keeps a 20% reserve for rework, because a plan without a buffer is a lie. A model with no price resolves to —; nothing is invented.
Plan and budget files are read-modify-write, so every mutation goes through one queue per project folder: two model calls that refresh the plan at the same moment cannot lose each other's work. A refresh keeps the stored routing comparison while the plan inputs are unchanged and drops it with a note when they moved, because a comparison priced for other units is a lie. plan.md is generated in the language the readout reports.
Which models are worth connecting
cost_scenarios prices the same plan under four routings: quality (the preferred route for every unit), connected (the cheapest route already listed), economy (the cheapest adequate model in the whole catalog — which may mean connecting a provider you do not use yet) and balanced (preferred route for units marked critical, economy elsewhere). Each scenario reports expected and worst-case totals, whether it fits the budget, and the providers it needs.
The recommendation names the cost drivers, ranks what switching would save per unit, and lists the three cheapest adequate alternatives with their context size and release date. Adequacy uses catalog facts — reasoning, tool calling, vision, context and output limits — and never a quality score, because the catalog has none. Free tiers are skipped unless asked for, and a cheaper model whose context is much smaller than your preferred route is flagged as narrower rather than quietly recommended.
Updating
The plugin is a profile dependency, so updating it is a pnpm operation in the profile directory — and one detail decides whether it works:
dsh plugin --profile web list                       # what is installed right now
dsh plugin --profile web add dsh-chat-cost@latest   # the normal path
dsh plugin --profile web update dsh-chat-cost       # within the declared range only
| Command | What actually happens |
|---|---|
add dsh-chat-cost@<version> |
installs exactly that version, immediately — the reliable path when a release is minutes old |
add dsh-chat-cost@latest |
resolves the latest tag; a version published minutes ago may be held back by pnpm's supply-chain policy, in which case the profile records an exception in pnpm-workspace.yaml or the previous version is installed |
update dsh-chat-cost |
moves only inside the range already declared in package.json; with an exact pin it does nothing |
add dsh-chat-cost (no range) |
resolves fresh and lands on latest; this is what re-installs the plugin if the profile lost it |
Restart the host afterwards: the profile's composition is assembled at boot, so a running host keeps the version it started with. To see which release is running without a terminal, hover the readout — the tooltip names it, and every cost-log record carries it in its plugin field ("plugin":"dsh-chat-cost@0.6.8"), which is how a ledger entry can be traced back to the release that wrote it.
Uninstall and recovery
dsh plugin --profile web remove dsh-chat-cost
Restart the host afterwards. Removing the row stops all of it — the readout, the badges under answers, the tools, the log writes. What is already written (the cost log, the plan, the budget) is yours and stays where it is.
If a plugin keeps the host from starting, the boot names it (plugin tree failed to load: …), and the fix is the same command with remove: the composition is assembled at load, so a plugin cannot be unloaded from a host that is already broken.
Compatibility
| Needs | Why |
|---|---|
| A DSH profile | the package is a bundle: dsh.bundle.patch points at cordis.patch.yml, and the profile reconciles it into dsh.profile.bundles |
| Node ≥ 20 | declared in engines; the plugin uses ESM and AbortSignal.timeout |
The loader contract apply(ctx, config) |
settings arrive as the second argument; reading them from ctx throws in this Cordis, and doing so once took the host down at boot |
The web shell slots conversation.composer.dock and conversation.chat.turnTail |
the composer readout and the per-answer badges; without them the Host half still prices, logs and answers its route |
| npm CLI ≥ 11.5.1 | only to release this package through npm trusted publishing, not to use it |
Limitations
- Reasoning tokens are billed as output by the providers and are counted as output here.
- Long-context tier prices published for some Gemini and Grok models are not applied yet; the base tier is used.
- A chat that the log has never seen and that is not open shows
—: the plugin prices what it can prove (the live session, or the log) and says so rather than estimating from a projection it cannot read. - The live readout counts only the tail of the log (
ledgerTailBytes, 2 MiB by default); older spend stays in the file and the summary reports the truncation. - Per-answer badges exist for turns the Host can price. A chat taken from the log has a total and no turn boundaries, so it shows no badges rather than invented ones.
- The write queue serializes the plugin's own writes. A human editing
plan.jsonat the moment the model writes it can still lose that edit; the file is small and meant to be reviewed, not co-edited.
License
MIT
No comments yet. Be the first to write one.