dsh-model-router
English | 中文
A DeepSeek Harness plugin that keeps a pool of models and routes every step to one of them with its reasoning effort set. Thinking stays on — DeepSeek rejects a thinking-enabled request whose history contains a tool call made with thinking off.
Routing table
| Step class | Decided by | Reasoning effort | Internal point |
|---|---|---|---|
trivial |
a clearly cheap intent (translate, rename, reformat) in a short step | low |
~50 |
standard |
a plain short request with no engineering cue | low |
~50 |
engineering |
engineering cues, code/diff/XML structure, or an agent tool loop | high |
~75 |
hard |
a dense engineering brief, or failures earned inside the task | high (max when allowMax) |
~75 / 100 |
high is the default ceiling. V4.1-Flash drives effort from an internal 1–100 scalar and exposes
three preset names; high corresponds to roughly 75, which is where the published effort curve is
still steep. Pushing past it costs about 1.6–1.8x the output tokens for a marginal gain.
Since v0.15.0 routes.<class>.effort accepts any of the nine effort words (off, none, minimal, low, medium, high, xhigh, max, ultra); a target that does not know a word gets the nearest tier, breaking ties upward (quality first). off and the max-class words still go through rule 5 and allowMax.
Authorization scopes, the model pool and task presets (v0.5)
control decides what the router owns, and a manual pick only counts in the scope that owns it: an
effort change stands down full/effort but not model, and a model switch stands down
full/model but not effort. While the router is down it stays out until the next command or the
composer control's resume action.
| Scope | Owns |
|---|---|
full — 模型+思考 / Model+Effort |
model + reasoning effort |
effort — 思考 / Effort |
one model you pick in the panel: the router only sets that model's thinking level |
model — 模型 / Model |
model only; the session keeps its thinking level |
In effort scope the panel first asks you to pick exactly one model
(POST /model-router/effort-model, reported by /state as effortModel / effectiveEffortModel).
Until you do, the router stays out entirely — it changes neither the model nor the effort. Once one is
bound, a manual model switch does not stand it down; changing the thinking level by hand does.
The client half registers its control into the shipped conversation.input.model seat at priority -1,
taking over the composer model cell; it carries the official model + effort sections plus the scope
switch, the resume action, the task-type picker, the model pool and the task presets, and talks to the
host over same-origin /model-router/* routes.
Model pool. Only pooled models are ever selected.
pool:
  - { id: deepseek-official/deepseek-flash, cost: 1, tier: cheap }
  - { id: deepseek-official/deepseek-v4-pro, cost: 8, tier: strong, maxPerTask: 3 }
  - { id: deepseek-official/deepseek-v4-flash-vision-exp, cost: 1, tags: [vision] }
  - { id: vendor-x/writer-pro, cost: 20, weights: { 小说续写: 95 } }
tier: strong is what hard steps and evidence escalation prefer; cost feeds
scoring.costPenalty; maxPerTask caps how many steps of one task may spend that entry
(per entry, or as a config-level maxPerTask.strong default for every strong entry that omits
its own; with neither, the default is unlimited); a vision tag is required for image steps
once any pooled model carries one.
Task presets. A user-defined task type with rules and per-model weights:
presets:
  小说续写:
    match: ["续写", "小说", "文风", "/chapter\\s+\\d+/i"]
    weights: { "vendor-x/writer-pro": 95, "deepseek-official/deepseek-v4-pro": 60 }
  代码重构:
    match: ["重构", "refactor", "架构"]
    weights: { "deepseek-official/deepseek-v4-pro": 90 }
A type pinned in the composer always wins; with nothing pinned the keyword rules run
(classifier: rules). Third-party models keep their own effort vocabulary: the router asks the
provider what it supports, picks the nearest level, and sends no effort field when the model
advertises none.
Opaque by default (the theme menu colour is translucent, which let the conversation
show through): 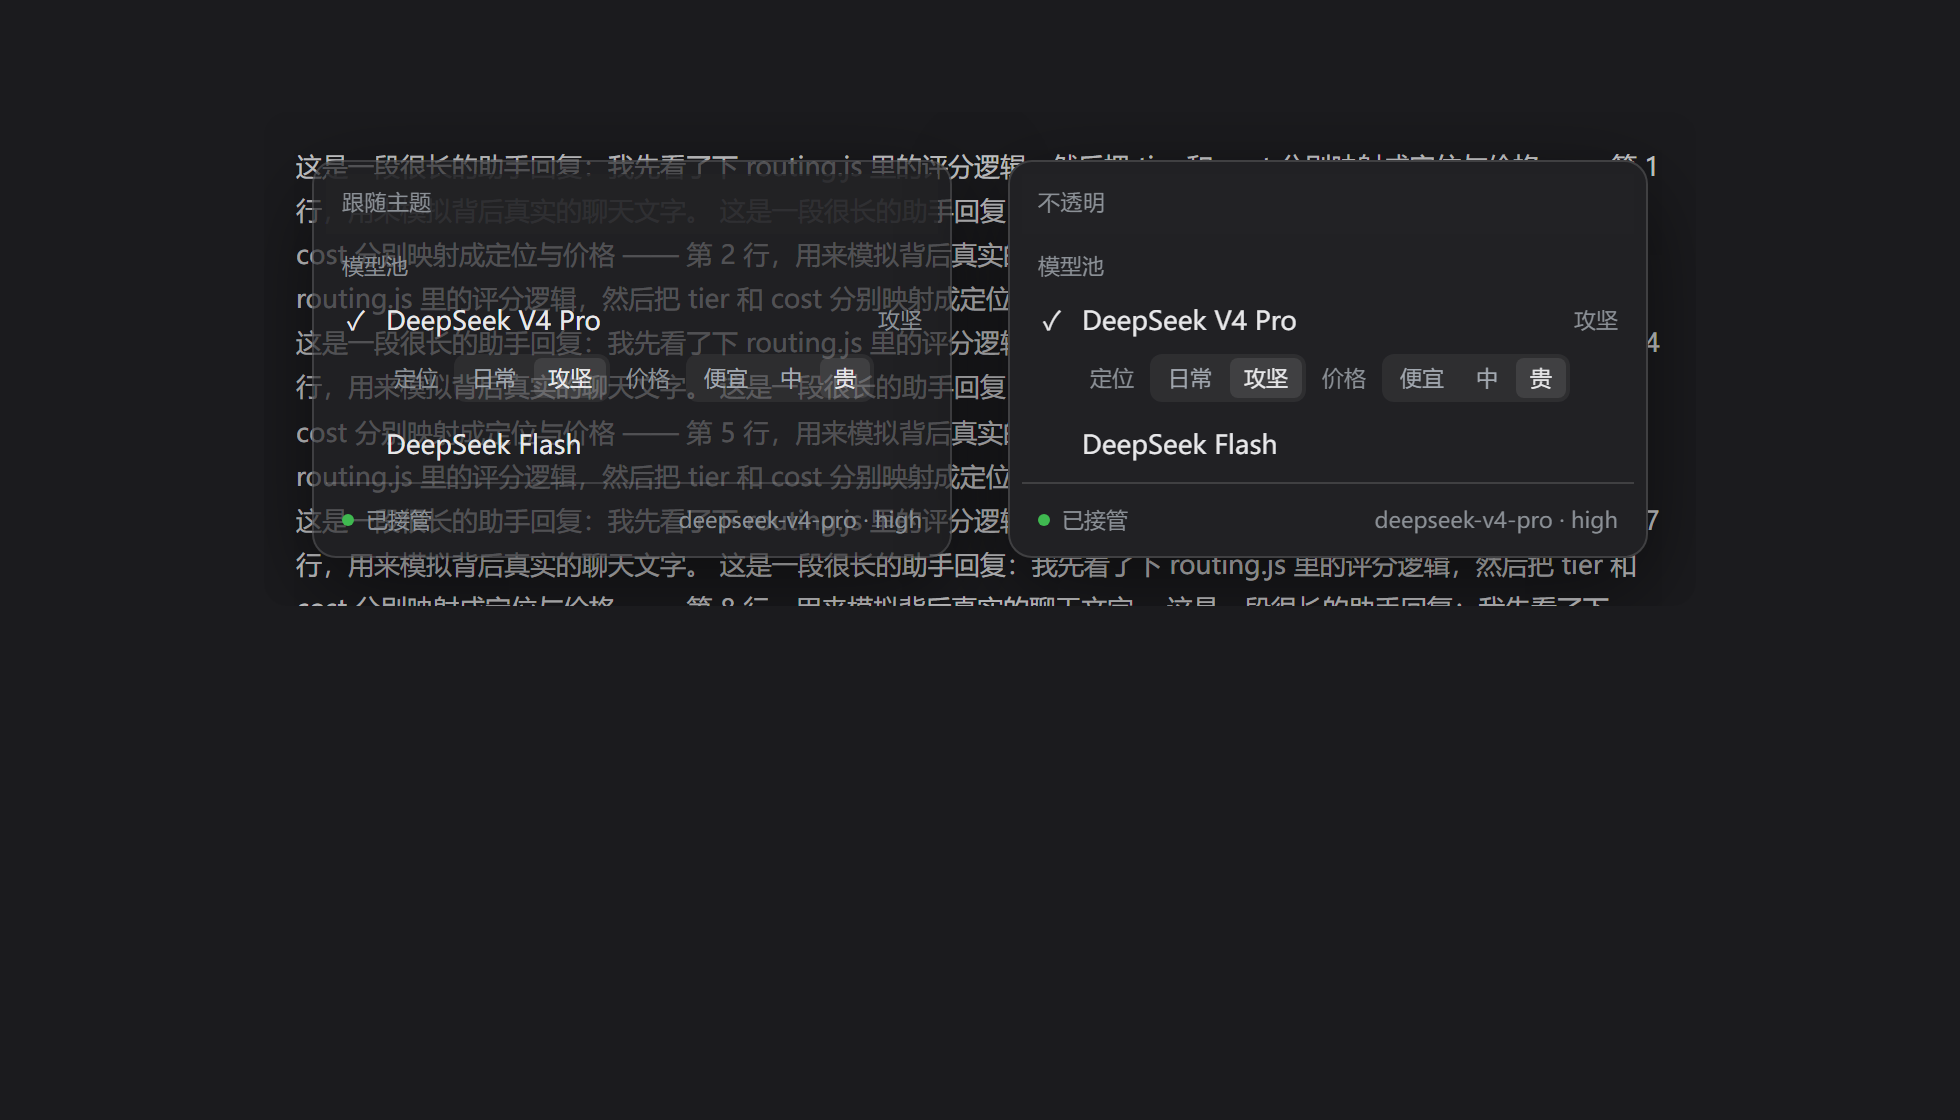
The router control is the composer model cell (v0.11.0)
The router's control registers into the shipped conversation.input.model seat at priority -1,
below the shipped ModelSelect (priority 0, from @deepseek-ai/dsh-client-ui-model-selection). The
slots engine renders the lowest priority, so the router's merged control takes over the composer model
cell and the composer shows a single control instead of a second chip beside the official picker.
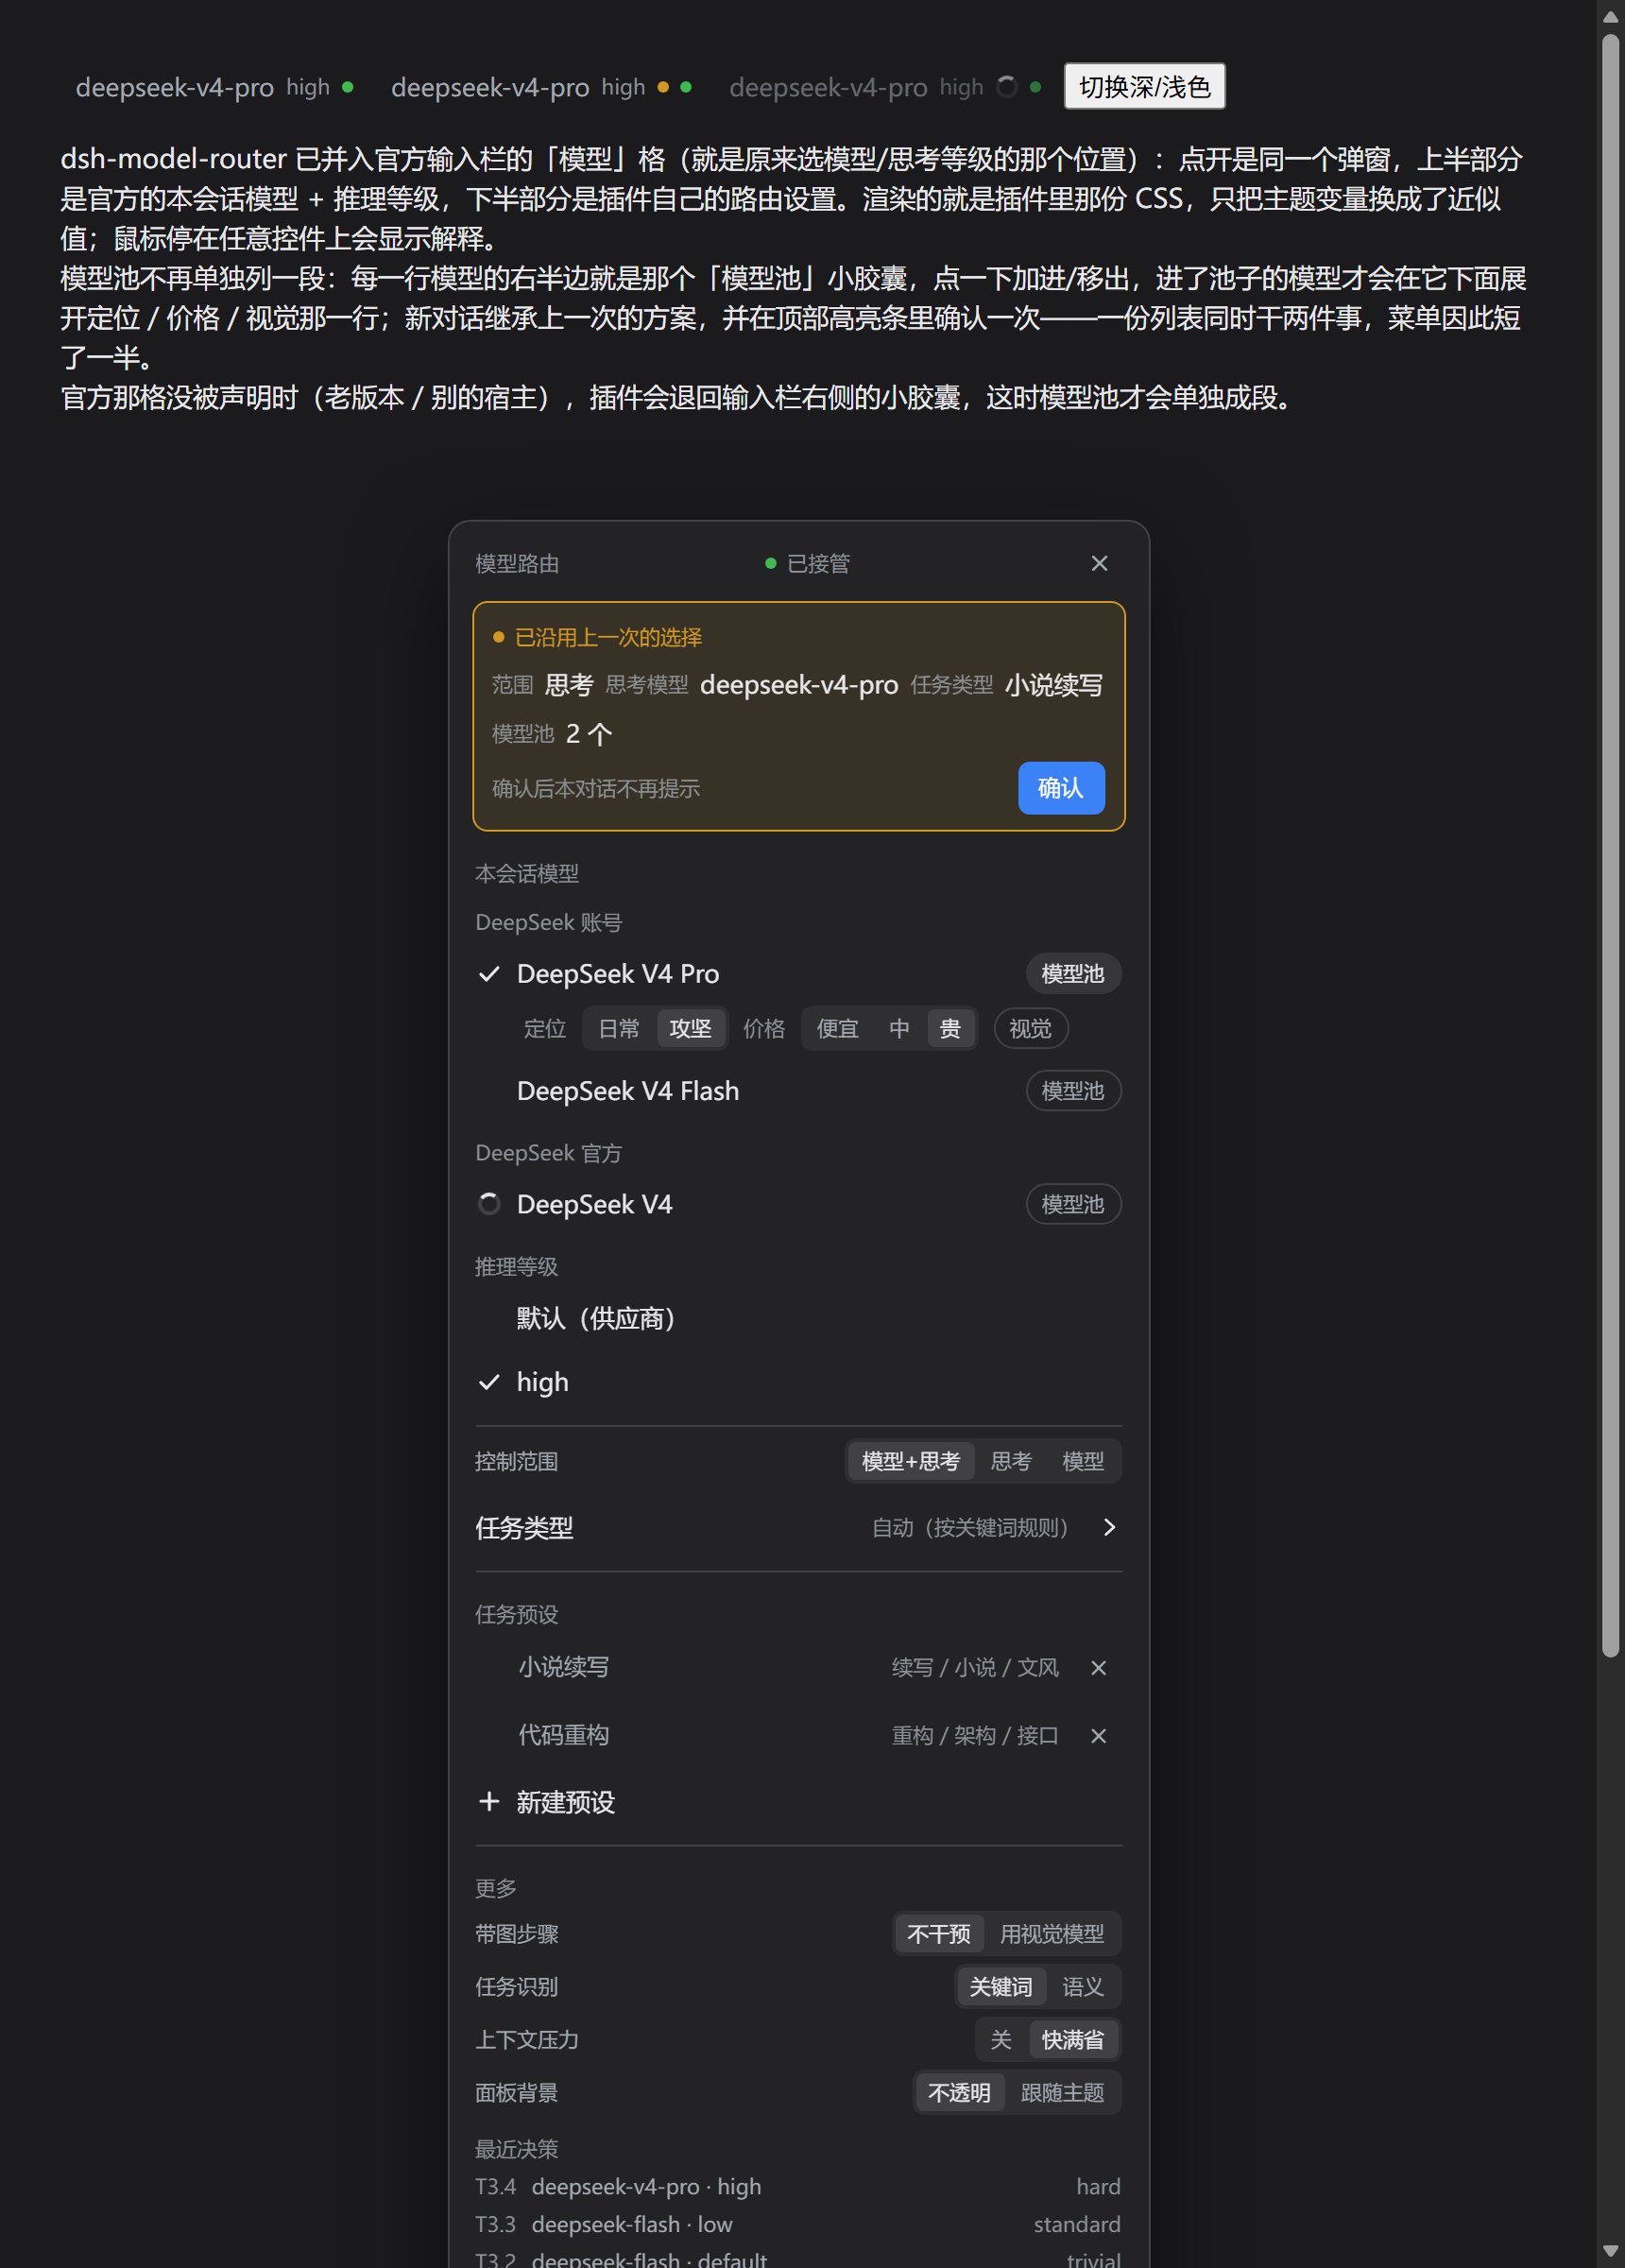
That one control keeps both halves. The official half is 本会话模型 / Session model and 推理等级 /
Reasoning effort, driven by the real ModelDirectory through props.directory.store subscribe,
props.load() and props.select({ provider, model, reasoningEffort }): provider/model groups, the
current row's check, the pending spinner, the provider-default row, catalog loading / error / retry, and
the official "model · effort" trigger label. Below it sit the router's own groups: the 接管 status,
控制范围 (模型+思考 / 思考 / 模型) and 任务类型, then the model list itself — the pool is folded into the
model rows: every session-model row carries a 模型池 / Model pool chip on its right, tapping it pools or
unpools that model, a pooled row expands its 定位 / 价格 / 视觉 controls underneath, and pool entries
whose provider group is not in the directory gather under 其他模型 / Other models with the manual
"type a model id" row. Rows are grouped by provider, each group header carrying 全加入 / Add all and
全移除 / Remove all, and the panel head carries 自动定价 / Auto price and 联网定价 / Fetch prices to fill
the 便宜 / 中 / 贵 cost level of entries you have not labelled by hand. Then 任务预设 and 更多. Every mutation goes to the host over same-origin
/model-router/* routes, and the per-call route row in the conversation is unchanged.
The old conversation.input.right chip (model-router:composer-control, order 20) is still registered,
but it self-retracts — it disposes itself as soon as the seat registration lands — so a normal host
renders an empty .right column and only ever sees the merged cell. A host that rejects or renames the
seat keeps the chip as its fallback.
0.10.0 tried this first and was rolled back in 0.10.1: the seat rendered blank and a restart failed to
boot. The root cause: cordis resolves nested services such as remote.session by walking fibers
upward from the calling fiber, so the client plugin itself must declare sessions, remote and
remote.session before a method may touch ModelDirectory.directoryFor(). The plugin-level inject is
now ["slots", "uiConversation", "sessions", "remote", "remote.session"].
Limits. This is a registration into the shipped seat, not a patch of the official component: the
official popup's internals (portal menu, search box, keyboard navigation, module CSS) are not
replicated, only its selection semantics. A DSH that stops declaring conversation.input.model makes
the seat registration fail silently and the small fallback chip takes over. Plugin source changes still
need a full dsh web/desktop restart.
New conversations inherit the last plan and confirm it (v0.13.0)
Every DSH start used to reset the panel to its defaults, and each new conversation decided its routing
plan on its own. The host now keeps the plan you last set — the scope, the bound effort model and the
pinned task type — under last in <profile>/.model-router/state.json, and a conversation with no
choice of its own inherits it. Choices stay per conversation: once you configure a conversation, its own
sessions entry wins and the other conversations are unaffected.
An inherited plan is not a decision you made in this conversation, so the panel opens with a
warn-tinted bar at the top: 已沿用上一次的选择 / carried over from your last choice, or
新对话:先确认这次的路由方案 / new conversation — confirm this routing plan when there was nothing to
inherit yet. It lists the effective 范围 / 思考模型 / 任务类型 / 模型池 with a 确认 / Confirm button
(POST /model-router/confirm { sessionId, plan }), and the composer trigger carries a pulsing amber dot
until you answer. Confirming records the plan key for that session — /state reports plan, planKey
and planConfirmed — and neither the bar nor the dot comes back in that conversation; changing the scope,
the bound model, the task type or the pool produces a different key and asks once more.
Multiple brands: grouping, automatic pricing and the cross-brand guard (v0.14.0)
The pool used to be a flat list, so a second brand took one click per model. The model list is now grouped by provider — every official directory group and every brand under 其他模型 / Other models — and each group header carries 全加入 / Add all and 全移除 / Remove all, so a whole brand enters or leaves the pool in one click.
Costs no longer have to be labelled by hand. A built-in relative-price classifier (lib/pricing.js,
pure and dependency-free) maps a model name onto 便宜 / 中 / 贵 (cost 1 / 4 / 8) for the common DeepSeek,
OpenAI, Anthropic, Google, Qwen and Llama families; 自动定价 / Auto price uses it plus any stored
OpenRouter snapshot, and 联网定价 / Fetch prices pulls a fresh snapshot first (20 s timeout). Each pool
entry records where its level came from in costSource (builtin | openrouter | manual), and an entry
you labelled by hand is never overwritten.
Crossing brands is its own decision. 跨品牌 / Cross-brand has three values — 允许 / 先问 / 禁止 (allow /
ask / off, default ask). Under ask, when the next step wants a model from another brand the host stays
on the current brand, exposes the candidate as state.cross.proposal, and the panel shows a propose bar
with 只切一次 / Switch once, 本会话允许 / Allow in this chat and 不再跨品牌 / Never cross brands. A pool
holding only another brand still routes (the guard needs a same-brand alternative), and the hysteresis
memory can no longer resurrect a model the guard excluded.
Routes: POST /model-router/cross { sessionId, action } (allow / once / never),
POST /model-router/pool/auto-price { fetch } and POST /model-router/prices; /state gains cross and
prices.
The panel matches the host (v0.6.4)
The composer control is styled with the harness's own tokens — the same 34px rows,
hover wash, glyph checks, segmented controls and popover elevation the built-in
menus use. Open docs/ui-preview.html in a browser (or see
docs/preview-dark.png / docs/preview-light.png)
to look at it without installing anything.


Everything is a click (v0.6.2)
The composer control is the whole configuration surface — no JSON or YAML:
| Section | What you do |
|---|---|
| mode | click 模型+思考 / 思考 / 模型; in 思考, pick the one model the router may tune; a manual pick adds a resume button |
| task type | pick auto (keyword rules) or one of your presets |
| model pool | tick models from the live catalog, then set tier / cost / vision with dropdowns |
| task presets | + 新建预设 → click a keyword pack (写作 / 代码 / 翻译 / 分析) or add a word → choose each pooled model's weight |
| more | image steps, task detection (rules / semantic), context pressure |
Everything persists in <profile>/.model-router/state.json through the same-origin
/model-router/* routes, so the profile row config stays optional.
Every call shows its route (v0.8.0)
Every tool call in the conversation now carries one compact line with the model and thinking level that actually ran that segment:
deepseek-official/deepseek-v4-pro · high
The host folds the session's own events into the modelRouterRoute session projection
(stateVersion 1): request/header gives the provider, model and effort in force, step/start
gives the turn and step, and tool/call records that pair under the call id. The effort is null
when the adapter owns the default, and those rows show the localized 默认 / default label.
The projection keeps the last 200 calls per session and drops the oldest.
The client half registers a model-router-route conversation Definition on every tool/call and
renders the row through the conversation.chat.node slot, anchored right after the call (+0.1).
It reads the projection defensively: a call id the host has not folded yet renders nothing rather
than borrowing another call's route. The line is a separate compact row next to the tool call —
see Limitations for why it is not a badge inside the tool row.
Images, session signals, subagents and the classifier (v0.6.0)
Images. imagePolicy: vision sends a task that carries an image to a vision model: the pool
entry tagged vision, or visionModel when set explicitly. The image is task-scoped — the next
command without one goes back to the normal tier.
Session signals. The router reads core session projections and lets them sharpen the choice:
| Signal | Effect |
|---|---|
active todo (todos) |
feeds task-type matching — a todo list states the work better than the prompt |
| context pressure | above signals.contextPressure (0–1) the cheap tier is preferred |
| token total | above signals.sessionTokens (0 = off) the cheap tier is preferred |
delegationDepth |
subagents prefer the cheap tier (subagent.preferCheap) |
Every decision records the signals it saw, so /router and the composer control can explain it.
/router prints the scope, engagement, pool, task type, the recent decisions and the task's
strong-tier spend; /router replay [n] prints the last n persisted decisions from disk (v0.15.0).
Classifier. classifier: llm makes one small call per turn to pick a preset
(classifierModel, effort off, classifierTimeoutMs), caches it for the turn and falls back to the
keyword rules on any failure. The default stays rules.
The observation baseline: telemetry, /stats, /router replay and ETag (v0.15.0)
v0.15.0 changes no routing result. It makes every routed step observable first.
Decision telemetry. Every routed step appends one router.decision/1 event to
<DSH_HOME>/storages/model-router/telemetry/decisions-YYYY-MM.jsonl (one file per month, rotated at 8 MB). The event
carries turn/step, stepClass, score and its scoreParts, the top-5 candidate scores, the actual chosen
provider/model/effort/tier/cost, reason, the cross outcome, the step's token delta and costUnits, and the
classifier's {used,type,confidence}. No prompt text, no message text and no absolute paths are stored; the session id
is hashed to sha256: plus 16 hex characters. Writes are batched on setImmediate, a failure is reported once and
disables telemetry, and a write can never affect the request path. DSH_MODEL_ROUTER_TELEMETRY=0 turns it off.
Cost units. costUnits = token delta × the model's pool cost / 1e6. It is the plugin's own accounting unit for
comparing steps and spotting trends, not a billed amount; /state.cost exposes sessionCostUnits and
taskCostUnits. Since 0.15.1 each event is also priced in USD from the shipped catalog (usage.costUsd), and
costUnits stays the pool-relative unit you set per entry.
GET /model-router/stats?since=&until=&limit=. Aggregates the JSONL into a fixed shape:
window{since,until,steps}, byClass, byModel, byEffort,
totals{costUnits,strongSteps,overrideRate,failedEscalations}. The default window is the last 7 days. It reads the
records from disk, so it survives restarts and covers sessions that are no longer open.
/router replay [n]. Prints the last n persisted decisions (default 10, max 50), one line each:
time/turn/step/model/effort/class/score/tokens/costUnits/reason. /router without replay still prints the live plan.
Cheaper panel polling. The panel now polls every 1200 ms (was 700) and uses ETag + If-None-Match: an unchanged
/state answers 304 with an empty body instead of re-parsing a large JSON document; /state.stateVersion is a
monotonic counter the client watches. On a host with no ETag it degrades to unconditional polling (0.14 behaviour).
DSH_MODEL_ROUTER_NO_ETAG=1 disables ETag for debugging.
Host self-check. At boot the plugin verifies its host contracts: sessionProjections is required, while a missing
webServer/commands/llm only degrades features. Missing pieces are logged once and surfaced in
GET /state.compat.missing, so the panel can say the host is incomplete.
Prices, hard dates and catalog drift (v0.15.1)
v0.15.1 prices observations; it does not change a route. Same model choice, same effort, same score - the golden snapshots are byte-identical to 0.15.0.
Dated prices. catalog/model-catalog.yaml records dated list prices (pricing, and pricing.next with an
effectiveFrom), the DeepSeek peak/off-peak schedule and the hard calendar. lib/catalog-pricing.js (exported as
./catalog-pricing) turns that data into numbers:
pricesAt(model, at)- the rate in force at an instant. Apricing.nextblock takes over on itseffectiveFromday, and DeepSeek's weekday 09:00-12:00 / 14:00-18:00 windows (Asia/Shanghai) bill at peak while every other hour bills at half.tokenSplit(before, after),tokenCost(split, price),usdCost(...)- two cumulative token projections become one step's input/output/cacheRead/cacheWrite/reasoning split, priced in the model's own currency and converted with the catalog'sfxRate.upcomingAlerts(at, {withinDays})andmodelMeta(model, at)- the hard dates inside a window, and the entry itself.
An unknown price stays null: a missing cache-write rate falls back to the fresh-input rate (that is how implicit
caching is billed), and a missing input or output rate makes the cost null rather than zero.
Priced decisions. router.decision/1 carries usage.split, usage.costUsd and a usage.price snapshot
(currency, unit, effectiveFrom, peak, source and the four rates in force), taken at the step's own timestamp - a
replayed step is priced at the rate that was actually charged, not at today's.
Cost ledger in /stats. totals and every by* row carry tokens, inputTokens, outputTokens,
cacheReadTokens, cacheWriteTokens, reasoningTokens, costUsd, pricedSteps and unpricedSteps. An event
written before 0.15.1 has no split and is counted as unpriced, never as free.
Watchlist and /state.catalog. The catalog keeps a top-level watchlist: for hard dates of models that are not in
the pool (the first entry is the 2026-12-31 end of GLM-4.5); the schema, scripts/check-catalog.mjs and
scripts/build-catalog.py all validate it, and a watchlist id may not shadow a known model id. GET /state.catalog
answers {evidenceDate, withinDays, alerts[{date, description, daysUntil}]} for the next 30 days; the panel shows a
warning dot on the trigger and in the panel head and lists at most three dates under the price note.
Weekly drift report. node scripts/catalog-diff.mjs compares the committed projection with the live OpenRouter
models API and writes a markdown report (--out, --now, --days, --offline <snapshot>, --json, --quiet,
--fail-on-drift). It is advisory - exit 0 by default - and it never edits the catalog: a human updates the YAML.
.github/workflows/catalog-diff.yml runs it every Monday at 03:00 UTC and uploads the report.
Cost-aware routing, shipped off (v0.16.0)
0.15.1 learned what a step costs. 0.16.0 prices the candidates: every pool entry gets one blended
USD-per-million-token rate from the shipped catalog for the instant of the step, and a cost term can join the
score. The flag ships off, so the route does not move - the ten golden snapshots are byte-identical to
0.15.1 - and what you get on day one is evidence: every step also records which model a cost-aware router would
have picked, and the panel and /stats show whether the two agree.
lib/pricing2.js(subpath./pricing2).blendedUsdPerMTok(model, at, mix)returns one rate for one model, blended over a token mix;DEFAULT_MIXis 50% fresh input / 35% cache read / 15% output andmixFromSplit(split)derives the mix a real session produced - a DeepSeek session reads cache for ~97% of its tokens, so pricing it at the default mix would overstate it about 2x.longContextRates(model, tokens, at)returns the long-context tier in force (whole_requestprices the whole prompt at the long rate,excessprices only the tokens past the threshold),stepCost(model, split, at)prices one split and matches the catalog price bit for bit whenever no long-context tier applies, andperCallCost(model, counts, at)prices per-1000-call rows such as DeepSeek Search/Fetch on their owneffectiveFrom. An unknown price staysnull; it is never rounded to zero.- The cost term.
scoring.costWeight(default 0.15) subtractscostWeight * 10 * (rate/floor - 1)capped atcostGuard.maxMultiple - 1(default 8x) - at most 10.5 points, against ahardBonusof 15 and anengineeringBonusof 8. Cost breaks ties and tilts same-tier choices; it does not outvote the task class.costGuard.unknownPricing: 'exclude'(the default) drops an entry the catalog cannot price instead of guessing,hardsteps are exempt from the multiple, and if the guard ever empties the pool the router retries once with cost awareness off (costFallback) - cost never leaves a session unrouted. - The shadow. With
costAwareoff, each routed step also runs the cost-aware choice and records it.GET /model-router/stategainscostAware:{enabled, costWeight, guard, mix, floorUsdPerMTok, entries[{id, tier, priced, usdPerMTok, currency, peak}], shadow}, whereshadowis{current, candidate, agree, currentUsdPerMTok, candidateUsdPerMTok, savedRatio, currentStepUsd, candidateStepUsd, costFallback}.GET /model-router/statssums it over the same window as the rest of the summary:shadow: {steps, agreeSteps, divergedSteps, agreementRate, pricedSteps, currentUsd, candidateUsd, savedUsd, savedRatio}. - The panel line. One caption under the price note:
cost shadow (off) · cost routing would pick X over Y · ~N% cheaper, orcost shadow (off) · cost routing also picks Xwhen the two agree, orcost shadow (on)once the flag is on. A host that sends nocostAwareblock renders nothing. - Turning it on.
costAware: truein the row config (the panel does not expose it yet). The same config then routes to the cheaper model whenever the cost term outweighs the score gap the shadow was reporting.
Channel health, spend limits and the peak window (v0.16.1)
0.16.0 answered what does this step cost. 0.16.1 answers is the channel that would serve it healthy, and is
this session still allowed to spend. Everything ships inert - channels.failover off, budget.mode: off,
peakPolicy: inform (a note, never a reroute) - so a router without those blocks behaves exactly as 0.16.0 and
the ten golden snapshots are unchanged.
- Channel health (
lib/channels.js). Every routed attempt is booked against a channel key: the pool entry'schannelwhen set (a second account on the same provider is its own channel), else its provider.classifyFailurereads the host's failure code and status -429/RATE_LIMITrotates,5xx/TIMEOUT/TRANSPORT/EMPTY_RESPONSEfails over, anything else is left alone.ChannelHealthkeeps a rolling window (20 attempts) per channel with an EWMA of TTFT; three consecutive failures bench the channel forcooldownMs(60 s) and one success clears it. Cooling is a demotion, not a ban: a benched entry sinks below healthy ones and keeps its score, so an all-benched pool still routes. - Failover. Off by default. With
channels.failover: truea failing request answers the host'sagent/request-errorwaterfall with{kind: 'retry'}- at mostmaxFailoversPerStep(1) per (turn, step) - and benches the channel that just failed so the retry cannot land back on it. When every channel of the current brand is benched the router may cross a brand boundary on its own, but only to an entry the catalog can price;crossProvider: 'never'still outranks failover. - Fingerprint and quarantine.
fingerprint(observed, expected)checks a response for what a cheap relay quietly gets wrong: amodelother than the one asked for, a usage block missing or all zeros, areasoning_contentthat never arrived, a TTFT pastmaxTtftMs. A channel that keeps failing that check is quarantined forchannels.quarantineMs(24 h) and named in/state.channels.quarantinedand the panel; a relay whose price is unknown is never entered automatically. - The spend guard (
lib/budget.js).budget.mode: 'inform' | 'block'withsessionTokens,sessionUsd,dayUsd,monthUsd;softRatio(0.8) marks the warning line, and a zero limit is not a limit.blockrefuses only a synthetic step - one carrying no fresh user message - by answeringagent/pre-stepwith{kind: 'reject'}; a step the user is waiting on always runs, and a refusal comes from the step, never from a retry loop.POST /model-router/budget(or/router budget [once]) releases one step, and the panel shows the same rows with a spend bar. - The peak window. DeepSeek charges double on weekdays 09:00-12:00 and 14:00-18:00.
peakPolicy: inform(the default) says so in the panel and/stats;shiftadditionally demotes the peak-priced entries for delegated (subagent) steps only - a step the user is sitting in front of is never delayed or downgraded for price. - Cross-brand proposals need a reason. 0.14.0 asked whenever the brands differed. A switch now has to be
clearly better (
crossCost.scoreMargin, 5 points) or clearly cheaper (crossCost.maxMultiple, 3x) than the best same-brand entry, or there has to be no same-brand entry left; the proposal carriessavingMultipleand itswhy, and every cross-brand step is still written to telemetry. - The panel. A budget dot (
data-budget=near|over) beside the catalog dot, a spend block with one row and one bar per active limit, a peak note, and one line naming benched and quarantined channels. A host that sends none of those blocks renders none of them.
channels:  { failover: false, failThreshold: 3, cooldownMs: 60000, quarantineMs: 86400000, fingerprint: true }
budget:    { mode: off, sessionTokens: 0, sessionUsd: 0, dayUsd: 0, monthUsd: 0, softRatio: 0.8 }
peakPolicy: inform    # off | inform | shift
crossCost: { maxMultiple: 3, scoreMargin: 5 }
Effort economics, part one: the ladder is auditable (v0.17.0)
The tier ladder used to live inside the scoring code. It is now a module (lib/effort.js, subpath ./effort) so the
question "did I ask for high and get high?" has an answer for every step.
LADDER is the documented eight tiers — off(0) minimal(25) low(50) medium(62) high(75) xhigh(86) max(100) ultra(105) —
and budgetForTier(tier, meta) turns one into a token budget (low 2048 … max 32768) from DEFAULT_BUDGETS, overridable
per model through effort.budgets in the catalog and always capped by maxOutput. Hosts that express depth as a token
budget can use it directly; the DeepSeek wire takes words, so the budget stays a capability statement there.
Every decision records how the tier arrived. explainMapping(tier, applied, meta) distinguishes four outcomes:
why |
meaning | example |
|---|---|---|
exact |
the model accepts the word itself | low → low |
alias |
the model documents a shorter vocabulary and aliases the word | medium → high on DeepSeek |
nearest |
the vocabulary has no such tier, so the closest one (ties go up) runs | xhigh → max on Kimi |
none |
the model advertises no reasoning effort at all | high → nothing |
The result is written to the decision event as effortMapped, published on /state.effort with the ladder and its
points, and appended to the route's reason whenever it is not exact — a collapse is never silent. /stats counts
them: totals.mappedSteps and totals.mappedShare at the top, effort.byClass for the mapped share per step class,
and effort.top for the most common from->to:why pairs. The panel adds one line (data-mr-effort) when the last
step's tier was not taken verbatim, and says nothing when it was.
Offline replay. /router replay [n] prints what was recorded. npm run replay re-derives what the current code and
pool would do with that same traffic:
node lib/replay.js                       # ~/.dsh/storages/model-router
node lib/replay.js --since 2026-10-20    # a window
node lib/replay.js --config pool.json     # a pool you are considering
node lib/replay.js --json                 # a report to diff
node lib/replay.js --fail-on-change       # exit 1 when a route or an effort moves
The CLI travels with the package (npx dsh-model-router-replay, or node node_modules/@neptune810/dsh-model-router/lib/replay.js after an install); npm run replay is just the repo shortcut.
The pool defaults to the one the traffic actually used, so a run of "no changes" proves the current code reproduces the
recorded routes; pointing --config at a pool with different weights answers "how much of last week would have routed
elsewhere?". Two things it cannot replay, on purpose: classification and presets both read the prompt text, which
telemetry never stores, so the recorded stepClass is taken as given and presets are not re-applied.
What is not in this version. costAware still defaults to false: the flip wants G3/G4 (≥7 days and ≥300 shadow
steps, at least one restart on a build that records the shadow). The feedback loop, the classifier v2 and ε-greedy are
0.17.1, together with the L2 experiment that decides whether the cost term becomes the default.
A feedback loop, a classifier that admits doubt, and exploration (v0.17.1)
Quality routing needs a signal the user can give in one press. The panel now carries three labels under the route they
judge (data-mr-feedback, the labels of FEEDBACK_LABELS: too expensive, too weak, just right), and pressing one posts
/model-router/feedback with { sessionId, label }. Nothing leaves the machine: the verdict is appended to
<storages>/model-router/telemetry/feedback.v1.jsonl beside the decision ledger, and the next routed step answers it —
outcome: "stayed" when the route that followed is the one the label judged, "moved" when it is not. That pair is the
weak signal the L2 experiment needs: a user who says "too expensive" and is then routed to the cheap model has answered
whether the label was a complaint or a request.
/stats.feedback aggregates the file rather than the session — totals and per-label counts, overrides (every label that
is not just-right) with their share, outcomes (how many were answered, and how many of those changed the route), and
byClass, so a class that keeps earning "too weak" is visible next to the class that keeps earning "too expensive".
The classifier is allowed to say "I am not sure" (lib/classifier2.js). parseVerdict reads a structured answer
({ class, confidence, family, evidence, signals }) out of the model's prose and decideVerdict turns it into a decision
that carries a source: the model's classification is used only when its confidence clears classifierMinConfidence
(0.6); below that the tier is raised one step instead of guessed, and the panel says so (data-mr-classifier). The call is
bounded — classifierAttempts (2), classifierTimeoutMs (2000) — and a circuit breaker opens after three failures and
leaves the router on pure rules for ten minutes. /state.classifier publishes the verdict, the escalate flag and the
breaker's snapshot: a classifier that is failing is a fact, never a silent fall back to unknown.
Exploration is opt-in and reproducible (lib/experiments.js). experiments.enabled is false; with it on,
planExperiment draws once per step and only on steps that are neither hard nor engineering — a step the router is
sure about is not a place to learn. apply is false too, so the default draw is a shadow: it is recorded
(/state.experiments.last, /stats.totals.experiments, the experiment field of the decision event) and the route does
not move. seed makes a run reproducible, epsilon (0.1) is the exploration share, and the panel names the arm when a
draw actually took the step.
classifier: llm            # rules by default
classifierMinConfidence: 0.6
classifierTimeoutMs: 2000
classifierAttempts: 2
experiments: { enabled: false, apply: false, epsilon: 0.1, seed: null }
What is not in this version. costAware still defaults to false: the flip wants G3/G4 (seven days and 300 priced
shadow steps, one restart on a build that records the shadow), and this repository records the threshold rather than
pretending to have met it. npm run replay is the honest way to answer the flip question on real traffic meanwhile.
What 1.0.0 actually promises (v1.0.0)
A 1.0 is a promise about what will not break, so this version is mostly about making the existing surface legible rather than adding capability.
- A versioned envelope. Every HTTP response from the panel's router — including the 403, 405 and
400 answers produced by the transport — now carries
"schemaVersion": 1. A reader can refuse an envelope it does not understand instead of guessing;docs/api.mddocuments the fifteen routes and the module entry points published throughpackage.json#exports. - The contract is tested, not just described.
test/contract.test.jsfails ifdocs/api.mdand the registered routes disagree, if a host event the plugin listens to is missing fromdocs/compat.md, if an export stops resolving or escapes the published directories, or if a response ever loses itsschemaVersion. - Degradation is named.
/state.compatreportsmissing(a capability without which routing cannot run, today onlysessionProjections) andoptional(webServer,commands,llm). The panel renders a note listing what is missing in the chat language, so a host that is too old shows as a shortcoming instead of looking fine while features silently do nothing. - An upgrade path with no migration.
docs/migration-0.14-to-1.0.mdlists every configuration key added since 0.14.2, notes that nothing needs migrating (the state file is read as-is), and records the one default that changed shape:peakPolicystarts atinform, which only ever prints. - Additive within 1.x. Modules may gain exports and
/statemay gain fields in a minor release; removing or repurposing either waits for 2.0.PUBLISHING.mdcovers the mechanics,CONTRIBUTING.mdthe checks a change must pass, andSECURITY.mdwhat the plugin stores and what it never reads.
Deliberately not in this version: splitting the browser bundle into a build artifact, and a CI matrix
against two host versions. Both are infrastructure work that does not change what the router decides,
and both are recorded as deferred in PLAN.md rather than implied by the version number.
The five rules
- No ratchet. Turn depth contributes no score by default (
scoring.turnPerPoint: 0) and tool calls are counted per task, so a long agent run does not drift toward the most expensive effort. A long run is not a harder task. Since 0.9.0 a tool loop is a score signal only — it no longer pins the class atengineering(scoring.toolCallClass). - Escalation needs evidence. Inside the current task,
escalateOnErrorsfailing tool results, or the same tool call retried with identical argumentsescalateOnRepeatstimes, step the class up — at mostmaxEscalationstimes. Nothing else moves it. maxis opt-in. Automatic routing never emitsmaxunlessallowMaxis set. The ceiling is enforced at the effort level, so even a hand-written route table asking formaxis clamped.- A manually selected
maxis demoted too (demoteManualMax), but only for models this plugin manages. Other models are left alone. EnablingallowMaxturns both clamps off. - Thinking stays on.
offis not an automatic route. DeepSeek's Messages API rejects a thinking-enabled request whose history contains an assistant tool call produced while thinking was disabled (The content[].thinking in the thinking mode must be passed back to the API). A cheap step can still call a tool, and the next step of the same task is an engineering tool loop, so oneoffstep followed by ahighstep failed the turn.trivialnow routes tolow, and any configured or manually selectedoffis raised tolowunlessallowThinkingOffis set. Recovery: if a conversation already contains such a turn (from an earlier version, or from a hand-selectedoff), the router detects it and keeps that session atoffinstead of failing every step, and logs one warning. Compact the session or start a new one to get thinking back.
Task boundaries come from agent/inbox/claimed, which is what actually opens a new piece of work.
When a task ends on an unresolved failure, the next one inherits a single hesitant step up — and only
if it is engineering or hard work. A one-line "translate this" never inherits a crash.
Tool loops no longer pin the effort at high (v0.9.0)
Before 0.9.0, classifyStep classified a step as engineering whenever its task had already seen one
tool call (cue agent tool loop), and engineering routes to high. Because the per-task tool
counter only resets when a new command is claimed, every step from the first tool call to the end of the
Agent run stayed at high. There was no way back down mid-loop: trivial needs a cheap cue and at
most 60 tokens, and standard required zero tool calls. And with allowMax: false (the default),
max is demoted to high, so hard and engineering applied the same effort — evidence
escalation changed nothing for a task that was already engineering.
Measured before: 帮我把这个文件里的日志改成中文 ran standard/low at 0 tools, then
engineering/high at 1, 3, 6, 12 and 25 tools for the rest of the task; 翻译一下这句话 with one
tool also went to high.
scoring.toolCallClass (default standard) decides whether a tool loop can earn the engineering class
on its own. With standard, tool activity still adds score (toolCallBase = 5, toolCallAt = 3,
toolCallBig = 8) but the brief — strong cues or structural text — decides the class, and
escalateOnErrors / escalateOnRepeats still escalate on evidence. Set it to engineering to
restore the old rule; any other value falls back to standard. Measured after: a casual brief with
tools stays standard/low throughout, an engineering brief stays engineering/high throughout.
hard still collapses to high unless allowMax: true, and routes.<class>.effort (for example
routes.engineering.effort: low) is the direct way to say how expensive a class may get.
Configuration
The plugin reads its config from its row in the profile's cordis.patch.yml:
- id: model-router
  config:
    mode: auto            # auto | off
    model: deepseek-flash
    allowMax: false       # true enables max for auto routing and manual selection alike
    maxFallback: high     # where max collapses when allowMax is false
    allowThinkingOff: false # true re-enables effort "off" (see rule 5: it breaks tool loops)
    control: full         # full | effort | model — what the router may choose
    manualOverride:
      yieldOnManual: true        # a manual pick stands; routing stands down
      resumeOnNextCommand: true  # …and re-engages on your next command
    pool: []              # whitelist; empty keeps the single `model` above
    presets: {}           # task type -> { match: [...], weights: { modelId: 0-100 } }
    scoring:
      costPenalty: 0.4    # how strongly relative cost subtracts from a pool score
      turnPerPoint: 0     # raise this to let long sessions weigh more (not recommended)
      toolCallClass: standard  # class a tool loop earns: standard (0.9.0) | engineering (pre-0.9.0)
    hysteresis:
      downAfter: 2        # quiet steps required before the effort steps down
    imagePolicy: keep     # keep | vision — route image tasks to a vision model
    visionModel: null     # explicit vision model; the pool's `vision` tag is used otherwise
    signals:
      todos: true         # let the active todo feed task-type matching
      contextPressure: 0.75  # above this occupancy, prefer the cheap tier (0 disables)
      sessionTokens: 0    # above this token total, prefer the cheap tier (0 disables)
    subagent:
      preferCheap: true   # delegated work stays cheap unless a preset says otherwise
    classifier: rules     # rules | llm — llm makes one small call per turn
    classifierModel: null # model used by the llm classifier (defaults to the first pool entry)
    classifierMinConfidence: 0 # ignore an LLM answer below this confidence; fall back to keywords (0 = accept all)
    escalateOnErrors: 2   # failed tool results needed to step up
    escalateOnRepeats: 3  # identical retries needed to step up
    routes:
      trivial:     { effort: low }   # "off" here is raised to low unless allowThinkingOff
      standard:    { effort: low }
      engineering: { effort: high }
      hard:        { effort: max }   # any of nine words; nearest tier when unsupported, ties go up
DSH_MODEL_ROUTER=off|auto overrides mode at boot.
| Key | Default | Meaning |
|---|---|---|
mode |
auto |
off passes every request through, except the manual-max clamp |
provider |
deepseek-official |
only this provider is ever touched |
model |
deepseek-flash |
the one model this plugin drives |
familyPattern |
^deepseek-(flash|v4) |
conversation models it may take over; a pro session is pulled back to flash |
allowMax |
false |
whether max is reachable at all |
maxFallback |
high |
what max collapses to |
demoteManualMax |
true |
also demote a manually selected max |
allowThinkingOff |
false |
allow effort off again; only for sessions that stay non-thinking |
control |
full |
what the router owns: full, effort or model |
manualOverride.yieldOnManual |
true |
a manual pick in the scope that owns it makes the router stand down |
manualOverride.resumeOnNextCommand |
true |
the next command re-engages it |
pool |
[] |
provider/model whitelist with cost/tier/tags/weights/maxPerTask |
maxPerTask.strong |
unlimited | Per-task step ceiling for strong entries; an entry's own maxPerTask wins |
presets |
{} |
task types with match rules and per-model weights |
scoring.costPenalty |
0.4 |
relative-cost weight in the pool score |
scoring.toolCallClass |
standard |
class a tool loop earns on its own: standard (0.9.0) or engineering (pre-0.9.0 rule); any other value falls back to standard |
hysteresis.downAfter |
2 |
quiet steps before a downgrade applies |
classifier |
rules |
rules or llm (one small call per turn, rules as fallback) |
classifierModel |
first pool entry | model the LLM classifier uses |
classifierMinConfidence |
0 |
ignore an LLM classifier answer below this confidence and fall back to keywords; prose answers without a confidence field are always accepted |
imagePolicy |
keep |
vision routes a task carrying an image to a vision model |
visionModel |
null |
explicit vision model id |
signals.todos |
true |
let the active todo feed task-type matching |
signals.contextPressure |
0.75 |
occupancy above which the cheap tier is preferred |
signals.sessionTokens |
0 |
token total above which the cheap tier is preferred |
subagent.preferCheap |
true |
delegated work prefers the cheap tier |
leaveImageSteps |
true |
steps carrying images keep the caller's model |
escalateOnErrors |
2 |
failure-evidence threshold |
escalateOnRepeats |
3 |
repeated-call threshold |
maxEscalations |
2 |
most classes a single task may climb |
carryUnresolved |
true |
carry one step up from an unresolved failure |
routes.<class>.effort |
low/low/high/high |
any of the nine effort words (v0.15.0); a target gets the nearest tier, ties go up; off and max-class words still pass the two guards |
Install
dsh plugin is a pnpm forwarder, so any pnpm specifier works. From the npm registry:
dsh plugin --profile web add @neptune810/dsh-model-router
or straight from the repository:
dsh plugin --profile web add github:Neptune810/dsh-model-router
Restart dsh web afterwards. Because the router registers listeners at boot, a reload is not
enough.
Upgrading from 0.6.x / 0.13: since 0.14.2 the shipped route table already sends trivial to low, so a profile
override routes.trivial.effort: low (added to cancel the old code default trivial -> off) can be deleted. A plugin
reinstall rewrites the patch layer, so that workaround was only ever temporary. The 0.14.3 state.json migrates to
version 2 on load and keeps the existing session records.
Requirements and compatibility
- Node 20 or newer.
engines.dshis declared as>=0.1.7-rc.2 <0.2.0; tested on@deepseek-ai/dsh0.1.7-rc.2. The plugin usesagent/request,agent/inbox/claimed,session.deriveMessages()and the session projections (modelSelection,todos,contextPressure,tokenUsage).- Do not declare
@deepseek-ai/*peerDependenciesin the plugin root. The host boot gate only reads peerDependencies and silently skips a plugin it cannot resolve instead of failing;engines.dshis used by dshmarket for install-time compatibility only and does not affect boot. The runtime defence is the startup self-check planned for 0.15+ (a missing contract switches to degraded and says so in the panel). - Only the web composer seat (
conversation.input.model) is verified; when the host does not declare that seat the panel falls back to theconversation.input.rightchip.
Limitations
- No config schema. Settings are read from the profile patch layer shown above and do not render
as a form in the settings UI. This is deliberate: a schema would require importing
@deepseek-ai/*packages, which a plugin installed beside the profile cannot resolve. - The router only touches the
deepseek-officialprovider and models matchingfamilyPattern. - The router control takes over the official model cell by registration, not by patching the
component. It registers into
conversation.input.modelat priority -1 (below the shippedModelSelectat 0), keeping the official model + effort sections inside its own panel. The oldconversation.input.rightchip (model-router:composer-control, order 20) self-retracts and is only a fallback for a host that rejects the seat. 0.10.0's first attempt shipped a blank cell and was rolled back in 0.10.1 because it had not declaredsessions/remote/remote.sessionon the plugin root. - The per-call route line is a separate small row anchored after the tool call, not a badge inside
the harness's own tool row or inside the thinking chain: a keyed slot replaces whatever it targets,
and the thinking chain exposes no child slot. A call the host has not folded yet shows nothing
rather than guessing. Plugin source changes only appear after you restart
dsh web.
Tests
node --test
421 tests. test/policy.test.js (40) covers classification, the absence of a ratchet, the
unreachable max, the refusal of off, evidence escalation, effort clamping, the poisoned-history
detector, tool-result error parsing, and the toolCallClass knob (default standard, engineering
restores the pre-0.9.0 rule, any other value coerces to standard); test/routing.test.js (26) covers the pool, preset
weights, vision filtering, maxPerTask, effort-vocabulary mapping and hysteresis, plus the cost term (the
weighted penalty and its cap), the cost guard's refusals (unpriced entry, unknown floor, hard exemption, the
multiple), the fallback that keeps a session routed, and the channel ordering (a benched entry sinks below a
healthy one, a channel rank breaks a tie, and an all-benched pool still picks its best);
test/channels.test.js (18) covers failure classification by status and by code, the rolling window and its
success rate, the TTFT EWMA and its discount, cooldown on the third failure, a success clearing it both ways, a
bench that records no failure, the stable ordering of orderChannels / channelRanks, and the fingerprint's
four refusals;
test/plugin.test.js (19) drives the host wiring with ctx/agent doubles, including a quiet tool loop
that stays at its brief's class instead of climbing to high; test/modes.test.js (34)
covers the three scopes, manual yield + resume, same-origin route guards (including a request whose Origin the
Desktop proxy stripped, and one carrying Origin: null), pool/preset editing, a
pinned task type, a third-party effort vocabulary, vision routing, subagent frugality, todo-driven
task types, context pressure, the /router command, the LLM classifier, the cross-brand guard (ask holds
and exposes a proposal, allow / once / never, a pool holding only the other brand still routes) and the
pricing routes; test/pricing.test.js (11) covers the price table, the USD band boundaries, OpenRouter
parsing and lookup, manual entries being left alone, and a snapshot beating the built-in rules;
test/effort-model.test.js (10) covers effort scope bound to one model (unbound stands off, binding
clears the pending flag, only the bound model's effort moves, the vocabulary comes from its own pool
entry, a session-less binding becomes the default) and the scope-aware manual yield (a model switch in
effort scope is not an override, an effort change is, model scope ignores effort, full scope reacts to
both) plus the route's clearing and validation; test/route-projection.test.js (12) covers the
projection contract (key/stateVersion, plain-JSON state, header folding with absent vs explicit null
effort, turn/step tracking, the header in force at a call, the fallback to the call's own values,
repeated call ids, the 200-entry cap in insertion order, integer-like call-id ordering, purity and a
JSON round-trip) plus the host registration and a host without the service; test/client.test.js (57)
loads the shipped browser bundle in a VM and asserts the registration (the route row, the composer chip
as a self-retracting fallback, and the merged seat on conversation.input.model at priority -1), the
closed trigger, the documented host routes, the route
Definition's match/anchor and its defensive read of the folded projection, the localized default label,
the seat face delegating to the session directory, the official selection semantics (model rows without
reasoningEffort, effort rows with it, the provider default, the current-row no-op, a locked session, an
unavailable subagent cell, a failed pick keeping its message, catalog errors offering a retry, and group
order), the router half's control/pool/settings payloads and the /effort-model binding, the pool
control that collapses the list and reopens it, and the catalog warning dot and its three-line note (and the silence of a host that
sends no catalog block), the cost shadow's caption (a divergence with its saving, the agreement form, the enabled flag, English, and the
silence of a host that sends no costAware block), the spend guard (a near-budget dot and its bar, an
overspent bar clamping to 100%, token rows, a zero limit and a malformed block staying silent), the peak note
under inform and shift (and its silence when off or off-peak), the benched/quarantined channel line in both
languages, the effort-mapping line (an alias, a nearest tier, a model that takes none, the silence of an exact
mapping and of a malformed block, and English), the feedback row (three labels posting the verdict, the recorded one marked, the next step's answer in both languages, and the silence of a host with no feedback report), the exploration line (a shadow draw, an applied draw, an exploit draw that says nothing, and English), the classifier line (a raised tier with its confidence, an open breaker outranking it, and the silence of a confident verdict), and the declared ui-chat seat and uiConversation service; test/store.test.js (6) covers state-file recovery (a corrupt file is backed up instead of
overwritten, a version 1 file migrates, a write failure is surfaced through storeHealth, the session
map is capped by least-recently-seen); test/routes.test.js (10) covers the panel token, the same-origin
read guard, path redaction, ETag/304 and /stats pass-through; test/release.test.js (8) covers the release gate (tag, version and
CHANGELOG agreement plus tarball contents); test/catalog.test.js (21) validates the shipped catalog
against its schema, pins the documented completeness warnings, proves the generator is deterministic, checks the
watchlist rules and covers findModel; test/catalog-pricing.test.js (18) covers the rate in force (pricing.next
on its day, the peak/off-peak windows), the token split, the null-not-zero price rules and the alert window;
test/catalog-diff.test.js (15) drives the drift report against a frozen OpenRouter snapshot; test/smoke.test.js (11) drives scripts/smoke.mjs against a fake host and checks the
PASS / WARN / SKIP / FAIL exit codes; test/telemetry.test.js (15) covers decision events landing on disk, monthly
files and 8 MB rotation, flush, corrupt-line tolerance, the aggregate shape, the token/USD ledger (a legacy event
counts as unpriced), the cost-shadow ledger (a malformed shadow is skipped, a step with no priced pair counts but
costs nothing), a once-only error, the off switch, and the effort-mapping counters;
test/observation.test.js (23) walks the routing surface end to end (/state fields, ETag 304, /stats aggregation,
/router replay, classifier confidence filtering, the nine-word route guards and scoreParts, and the cost
shadow: the model a cost-aware router would have picked, the agreement a cheap-live route records, the flag
actually moving the route, and a pool the catalog cannot price recording neither a rate nor a shadow; plus the
0.16.1 surface: the spend guard refusing a synthetic step and releasing one, an inform budget that only warns, a
benched channel moving the retry to another provider, failover off leaving the route alone, and the cross-brand
proposal appearing only when the switch is clearly better or cheaper);
test/pricing2.test.js (15) covers the blended rate (peak, off-peak and the weekend, cache-only and output-only
mixes), the long-context tiers (the largest threshold wins, effectiveFrom is respected, whole_request vs
excess), stepCost matching the catalog price at three instants, and the per-call rows before and after
their effectiveFrom; test/feedback.test.js (8) covers the three labels and their aliases, the normalized record (note folding, length caps, absent provider), the outcome pair, a reader that skips bad lines, the aggregate (per label, per class, the override share, the answered outcomes), and a log that is switched off writing nothing; test/classifier2.test.js (6) covers the structured verdict behind prose, the confidence gate, the raise-instead-of-guess answer, the bounded retries and the breaker that opens after three failures; test/experiments.test.js (7) covers which step classes may be explored, a seeded draw, every reason a draw is refused, exploit vs explore, the epsilon clamp and the per-arm report; test/effort.test.js (7) covers the eight-tier ladder and its points, the unknown word ranking as high,
the budget table and its per-model overrides, the maxOutput cap, the four why answers, the per-class and per-pair
summary and malformed input; test/replay.test.js (5) drives lib/replay.js over a frozen ledger (an unchanged
replay, a step that would route elsewhere today, --fail-on-change, a config exposing an alias collapse, the
--since / --until window, and the two exit-2 paths); test/golden.test.js (11) freezes ten representative routing outcomes (rewritten only
with GOLDEN_UPDATE=1), so unintended drift fails; test/contract.test.js (7) pins the 1.0
contract itself — every response carries schemaVersion (refusals included), the routes in
docs/api.md are exactly the registered ones, every host event the plugin listens to appears in
docs/compat.md, every published entry point resolves and lives in a published directory, the
package declares the host it supports and never peers on it, the 1.0 documentation set exists,
and the degradations the panel names stay documented.
The model catalog
Routing thresholds are code; model facts are data. catalog/model-catalog.yaml is the source of truth
for what each addressable model costs, which reasoning-effort words it accepts, what its context window is,
which channels carry it and what is scheduled to change — 19 models with an evidence date, written so that
unknown stays unknown instead of being guessed. It is validated against
schema/model-catalog.schema.json and compiled into lib/catalog.js by scripts/build-catalog.py.
The generated module is committed and never edited by hand.
py -3 scripts/build-catalog.py          # regenerate lib/catalog.js from the YAML
py -3 scripts/build-catalog.py --check  # fail if the two disagree
node scripts/check-catalog.mjs          # structural validation, no Python needed
Since 0.15.1 the router does read it, but only for money and dates: each decision is priced at the rate in force at
that step (lib/catalog-pricing.js), and /state.catalog reports the hard dates coming up. Since 0.16.0 the catalog
rates are also what a cost-aware score and the shadow use (lib/pricing2.js), and since 0.16.1 they decide which
candidate a failover may cross into - an entry the catalog cannot price is never entered automatically.
Release checks
Every release goes through the same gate locally and in CI:
npm test                                # all tests
npm run release:gate                    # tag = package.json = CHANGELOG, tarball contents
py -3 scripts/build-catalog.py --check
scripts/check-release.mjs refuses a tarball that misses a promised file or ships test sources, and it is
the reason a version bump, its CHANGELOG heading and the pushed tag can no longer drift apart. CI runs the
suite on Node 20, 22 and 24; a tag run publishes with npm trusted publishing and a provenance attestation.
See PUBLISHING.md for the full checklist and the rollback steps.
License
MIT
No comments yet. Be the first to write one.