DSH-Paper-DeepRead
English | 中文
A DeepSeek Harness (dsh) Web plugin that ships a complete deep-read paper library and the skill that produces it. One install gives you a sidebar panel with interactive paper reading reports, the original PDFs beside them, and a model tool that can find the right paper in the same catalogue.
What it is
DSH-Paper-DeepRead bundles two things into one installable dsh bundle:
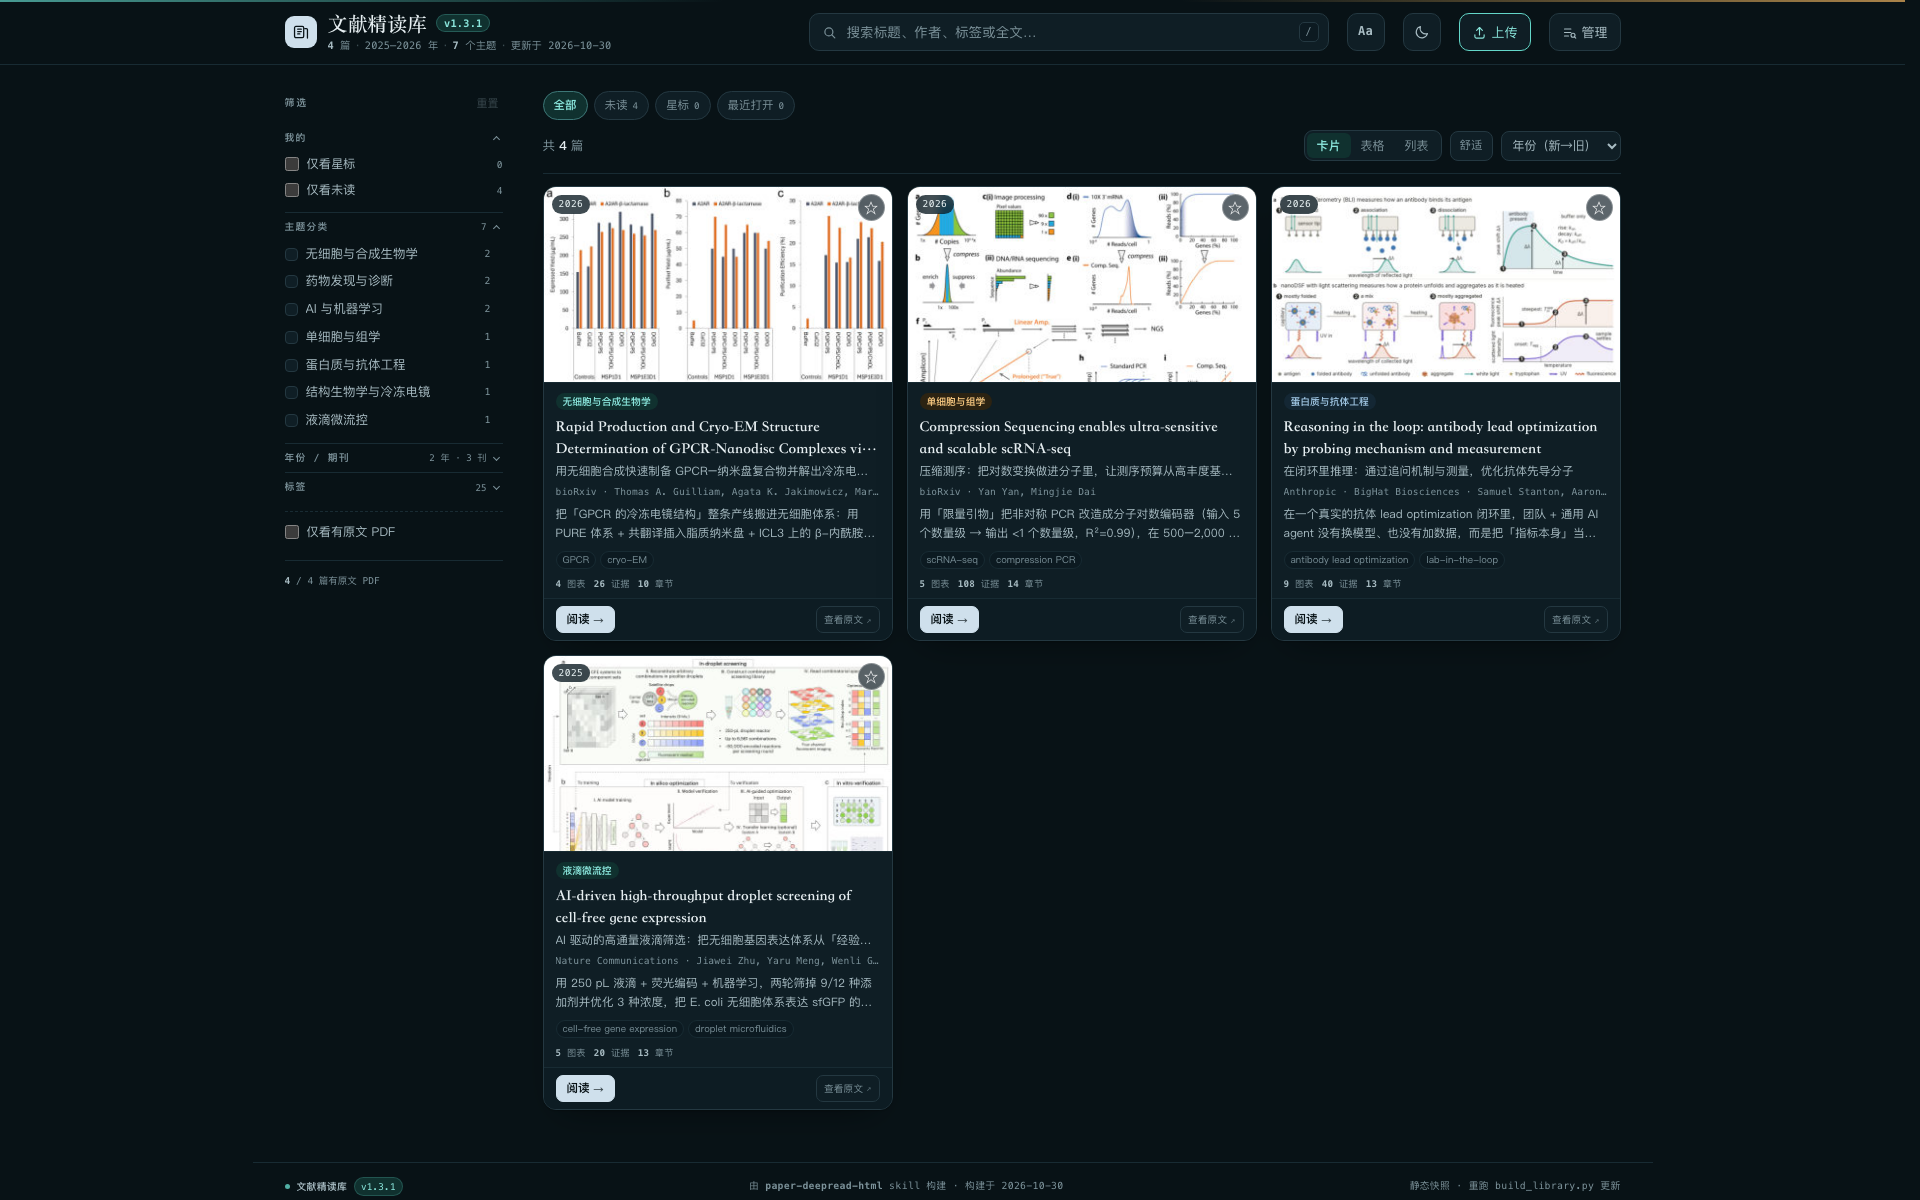
- 文献精读库 / Paper Deepread library — a static site with four deep-read papers
(2025–2026, Nature Communications / bioRxiv / Anthropic · BigHat Biosciences). Every
paper has an interactive single-file HTML report with original figure crops, redrawn
SVG schematics, a claims ledger, a critical appraisal, and the untouched source PDF.
The library is served by this plugin at
/paper-deepread/index.html. paper-deepread-htmlskill — the full deep-read pipeline (SKILL.md, build/ingest scripts, report and library templates, references). The plugin installs it into~/.dsh/skills/paper-deepread-htmlwhen that directory is missing, and since v1.2.0 keeps it in sync with the bundled version through a hash-tracked, backup-first update policy: user edits are always preserved, andskillSync: "keep"disables updates.
The plugin also exposes the paper_deepread model tool, so an agent can list the
bundled papers, substring-search titles / Chinese titles / journals / tags / summaries /
full text, and read a report locally or open its Web URL. Two more tools
(paper_deepread_uploads, paper_deepread_reports) drive the upload -> ingest -> build
pipeline described below.
Features
- Sidebar entry Paper Deepread that opens a full-height library page in the main panel, with an open in new tab link and a reload button.
- Host route
GET|HEAD /paper-deepread/*serving the bundledlibrary/directory with correct content types,Content-Length, percent-decoded paths (spaces,·, Chinese characters), and traversal protection. - Model tool
paper_deepreadreturning paper ids, bilingual titles, journals, tags, TL;DRs, absolute report/PDF paths, and encoded Web URLs. - Skill self-registration that never fails plugin activation.
- Skill version sync (v1.2.0) — reads
version:from the SKILL.md frontmatter, records a content hash in<dataDir>/skill-state.json, updates only unmodified copies the plugin installed itself (old version backed up to<skillsDir>/.backup/), never downgrades, and reportsskillVersion/installedSkillVersionin/api/stateand thepaper_deepreadtool. - Optional auto deep-read pipeline (v1.2.0) — with
siteUrlconfigured, the 上传 tab shows an 自动精读 card: worker/queue status from the site's/api/health, a raw PDF uploader throughPOST /paper-deepread/api/site/upload(filename/content-type/optional upload token forwarded, 120 s timeout), duplicate / possible-duplicate feedback from the site response, and a link to<siteUrl>/manage.html. - No runtime dependencies: the host imports only Node built-ins plus the
@deepseek-ai/dsh-toolspeer; the browser half is a single dependency-free file.
Requirements
- DeepSeek Harness
0.2.0-rc.2−0.2.1-rc.3 - Node.js
>= 24 - The
webprofile (the plugin needswebServerandtools)
Version matrix
| Component | Version |
|---|---|
Deep-read site backend (deploy/serve.py) |
1.5.0 |
| 文献精读库 library index | 1.5.0 |
| DSH-Paper-DeepRead plugin (this package) | 1.5.2 |
Bundled paper-deepread-html skill |
1.5.1 |
The plugin works standalone. The 自动精读 card additionally needs a running site ≥ 1.4.0
(the /api/health endpoint plus the upload-token and queue controls).
Install
Download dsh-paper-deepread-1.5.2.tgz from the GitHub release, then install it into the
Web profile:
dsh plugin --profile web add ./dsh-paper-deepread-1.5.2.tgz
Restart the Web UI:
dsh web
Then open http://127.0.0.1:3080 and click the Paper Deepread icon in the left sidebar. The bundled library is also reachable directly at http://127.0.0.1:3080/paper-deepread/index.html.
See docs/install.md for the exact commands, verification steps, and uninstall instructions.
Upload papers and manage reports (v1.1.0)
The panel now has three tabs: 文献库 | 上传 | 报告管理.
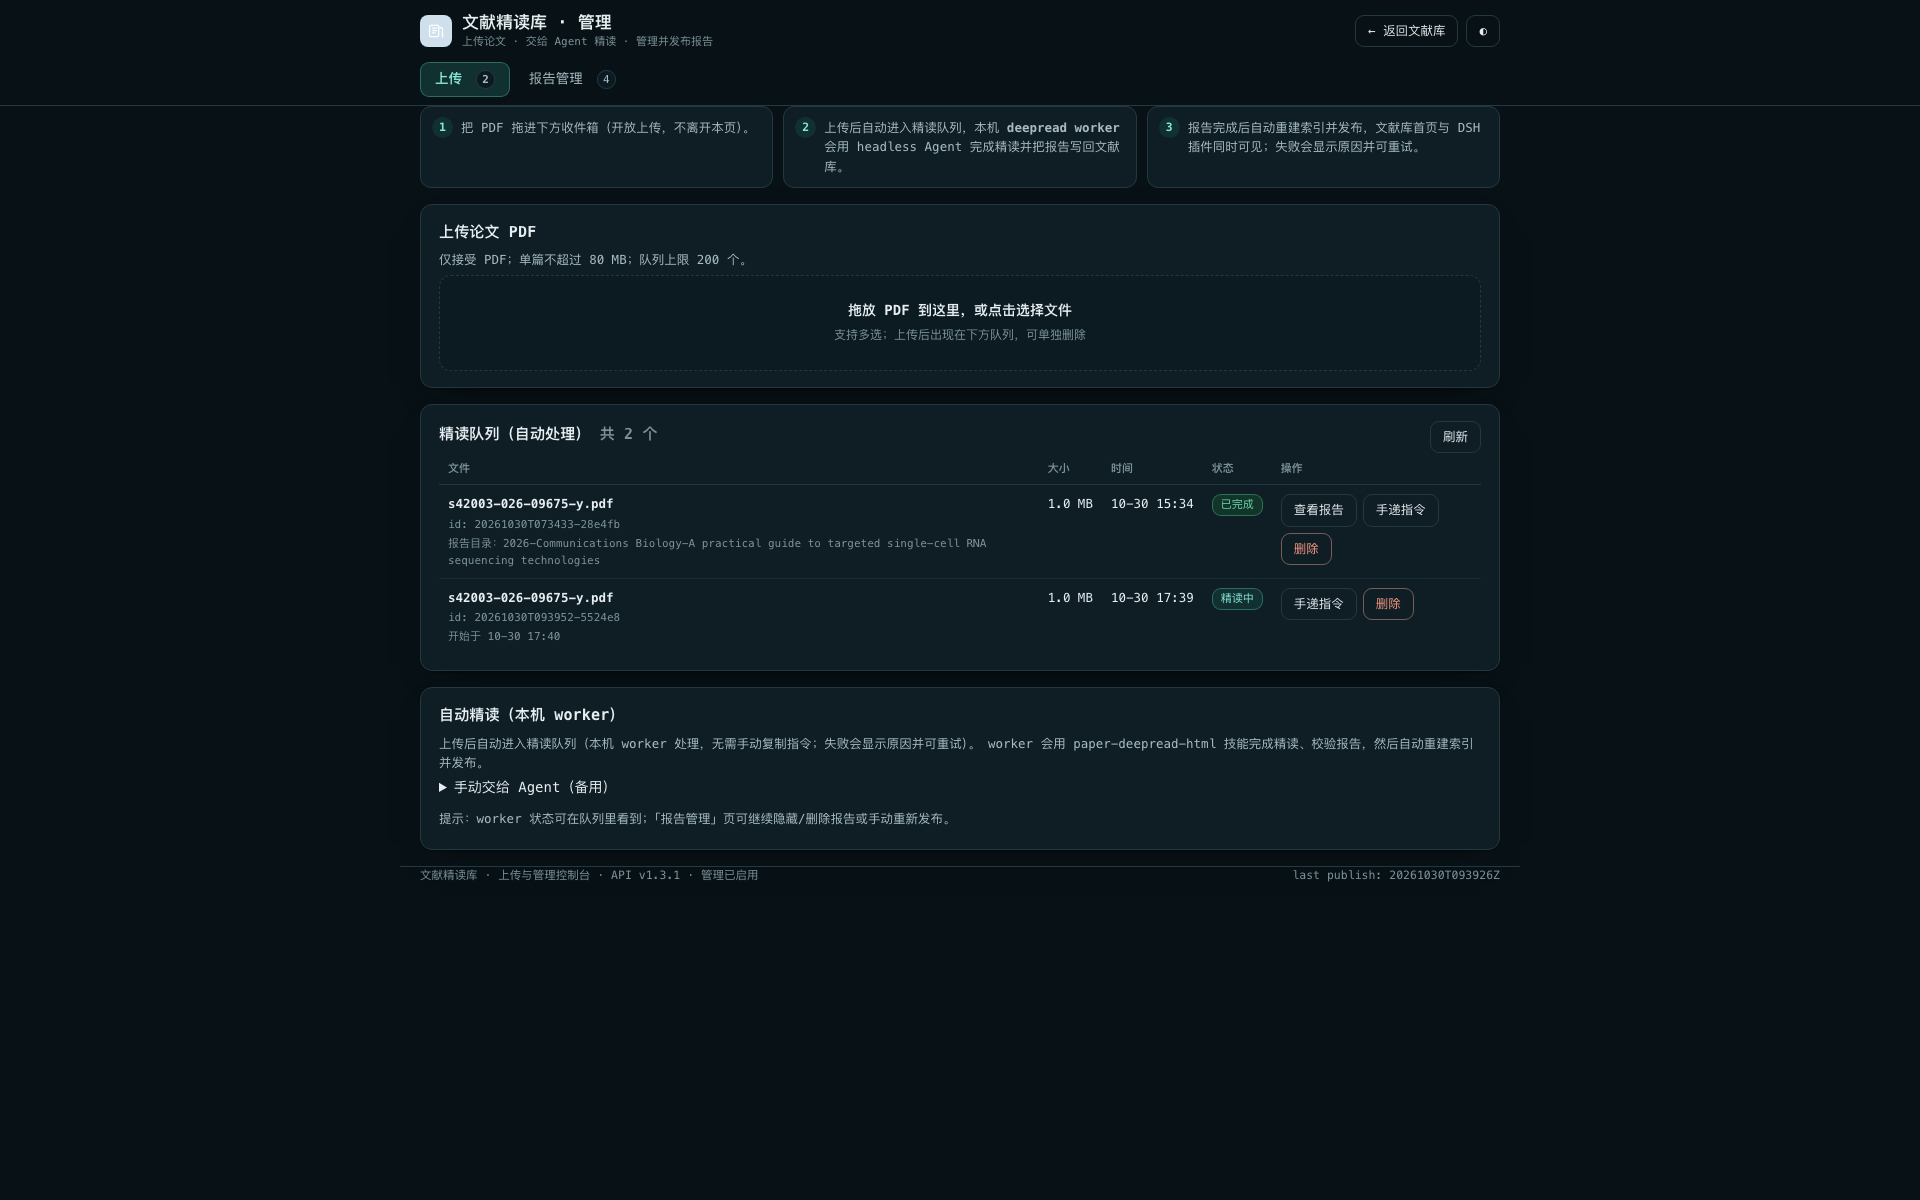
- Upload — drag & drop (or pick) one or more PDFs. Files go into the managed
inbox at
<dataDir>/uploads/<id>.pdf(80 MB default limit,%PDF-magic checked), with per-file progress and a list of uploads/statuses you can delete. - Agent handoff — the plugin never calls a model. The upload tab shows a prefilled
instruction; copy it into a chat so an agent calls
paper_deepread_uploads(list/ingest/env/delete) andpaper_deepread_reports(list/build/rebuild/delete/hide) to run the bundled skill and assemble the report. - Standalone
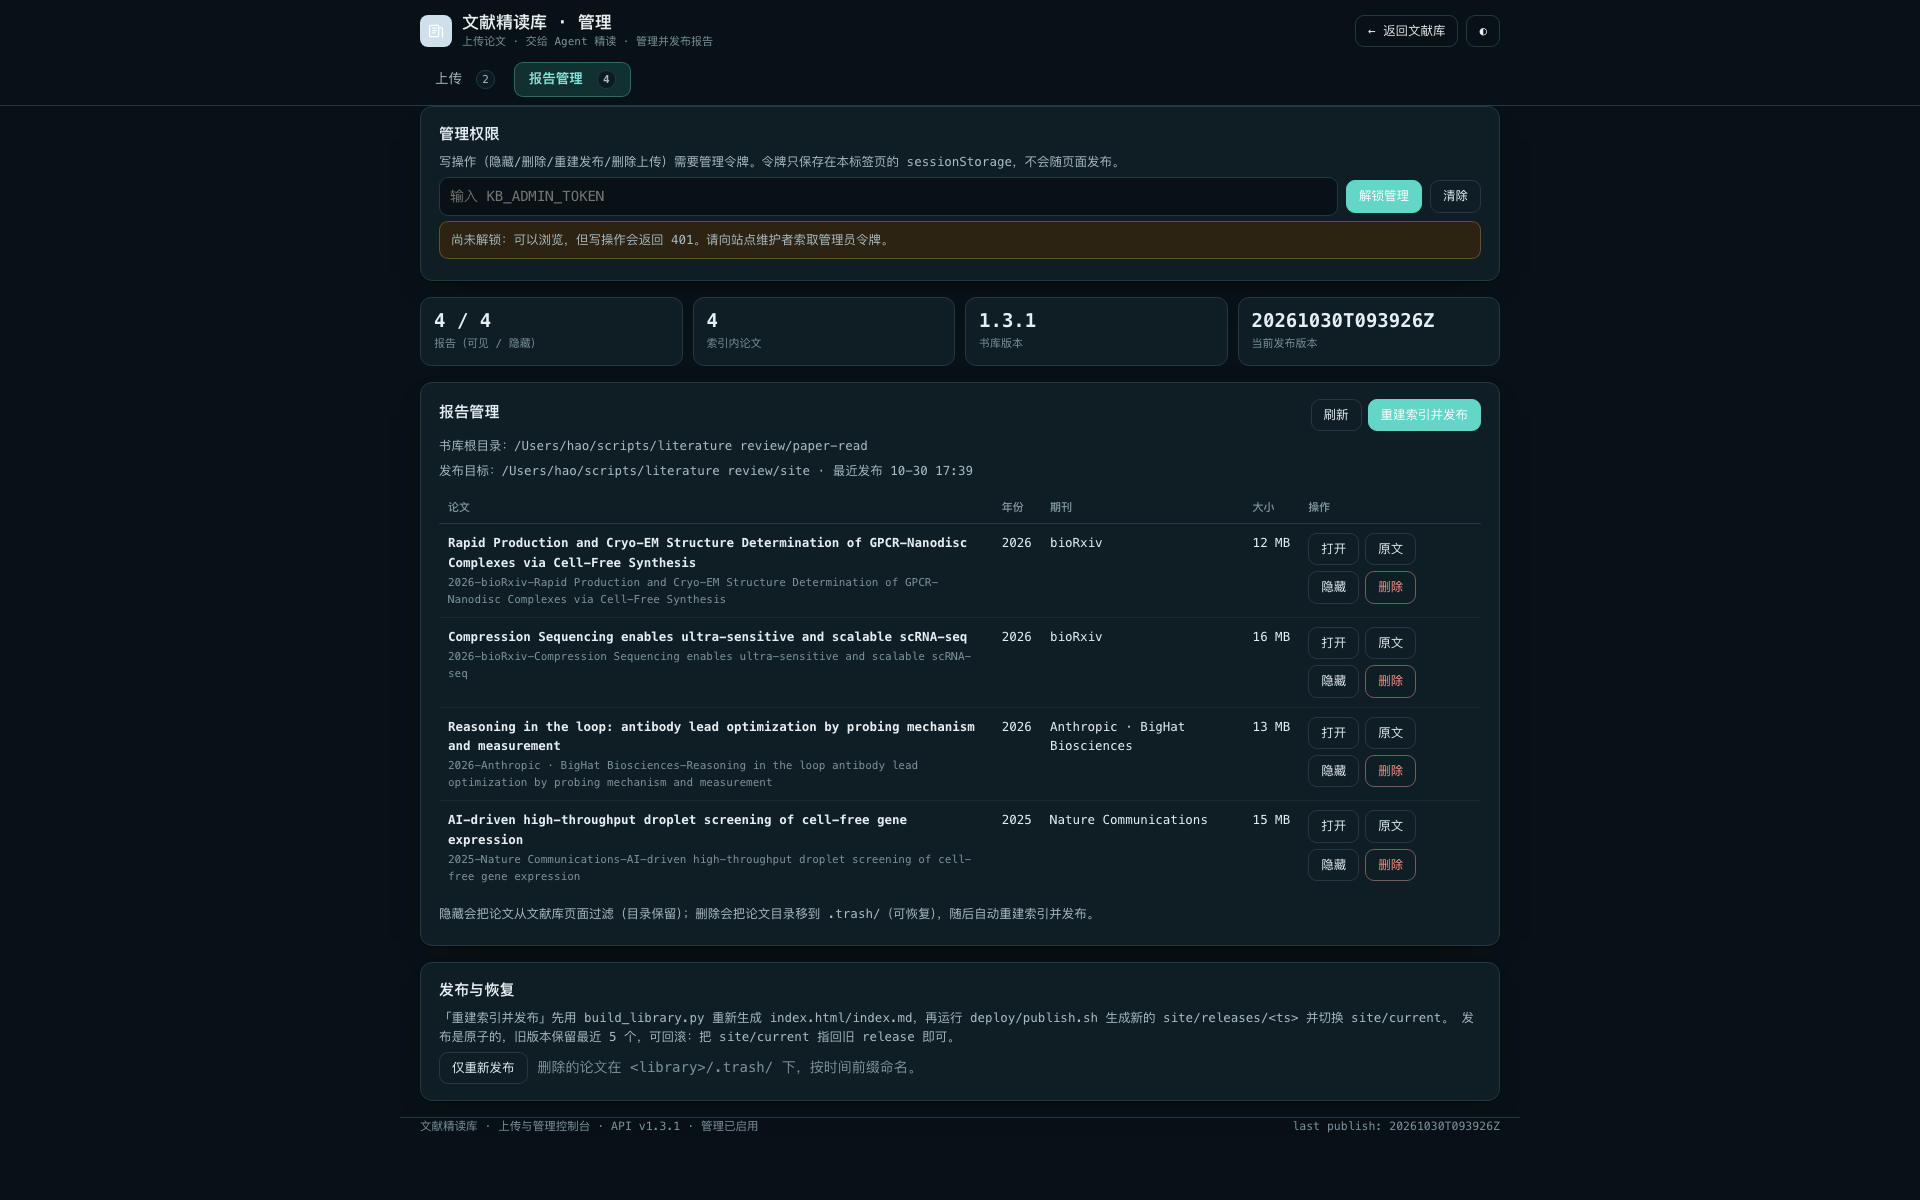
manage.html— the bundled library page now has 「上传」「管理」 header entries that open the same self-contained management console (library/manage.html). It works at the site root (/manage.html→ site API) and inside the plugin (/paper-deepread/manage.html→ plugin API) because every API URL is relative. - Report management — a table of reports with open/report-raw links, hide/unhide
(current-window filtering via
library.json), delete one report directory, and a one-click 重建索引 that deterministically rebuildsindex.html/index.mdwithbuild_library.py(no model involved).
The managed library lives in a data directory ($DSH_HOME/paper-deepread by default):
~/.dsh/paper-deepread/
├── library/          seeded once from the packaged 文献精读库, then user-owned
├── uploads/          uploaded PDFs waiting to be deep-read
├── work/<id>/        ingest output + agent-authored report sources
├── state.json        upload inbox and statuses
├── skill-state.json  installed skill version + content hash (v1.2.0)
└── .seed.json        one-time seed marker
Report statuses flow uploaded -> ingested -> reported (failed carries the error).
If you set the legacy libraryDir option, that directory is used as the managed root
and seeding is skipped, so you can point the plugin at an existing local 文献精读库.
自动精读 — hand PDFs to the standalone site (v1.2.0)
The plugin can also drive a running Paper Deepread site (deploy/serve.py), which
runs a background worker and publishes reports into its own library. Configure its base
URL and the 上传 tab gains an 自动精读 card at the top:
config:
  siteUrl: http://127.0.0.1:8080
- Status strip — worker online/offline (green/red dot), queue
uploaded/processingcounts, library count, and site version, refreshed every 8 s fromGET /paper-deepread/api/site/health(the host proxies<siteUrl>/api/health, 5 s timeout, 5 s cache). - Uploader — drag & drop or pick PDFs; each file is posted to
POST /paper-deepread/api/site/upload, which forwards the raw body withX-Filename,Content-Type, and (when set in the card's optional token field)X-KB-Upload-Tokento<siteUrl>/api/uploadwith a 120 s timeout, then returns the site JSON verbatim. Upload progress is shown per file; the worker picks the file up automatically. - Feedback — duplicate uploads show the site message ("文献库中已有…", "同一 PDF 已在
队列中…") as a warning, possible duplicates show the matched title,
401 UPLOAD_TOKEN_REQUIREDasks for the upload token (stored in this tab's sessionStorage only), and429 RATE_LIMITED/ queue-full messages are shown as returned by the site. - Links — 打开站点管理台 →
<siteUrl>/manage.html, 打开站点书库 →<siteUrl>/.
The plugin never stores site credentials; the token is per-request browser state only.
Without siteUrl the card is hidden and the 上传 tab is exactly the v1.1.6 local inbox
and agent-handoff workflow.
Skill version sync (v1.2.0)
The bundled skill declares a version: field in its SKILL.md frontmatter (currently
1.2.0). On every activation the plugin compares it with the installed copy under
~/.dsh/skills/paper-deepread-html:
| Installed copy | Behaviour |
|---|---|
| missing | install the bundled skill, record version + content hash |
skillSync: "keep" |
never update an existing copy (log only) |
| version == bundled | skip |
| version > bundled | skip (never downgrade) |
| version < bundled, tree byte-identical to the recorded hash | back up to <skillsDir>/.backup/paper-deepread-html-<oldVersion>-<UTC>/, copy the bundled tree, refresh the hash |
| version < bundled, tree modified or not tracked | keep the user's copy and warn — no silent overwrite |
skill-state.json in the managed data directory records the installed version, the
content hash, the plugin package version, and installedAt. Copies that existed before
v1.2.0 have no recorded hash and are therefore treated as user-managed (kept, warned);
delete the installed directory once if you want the plugin to manage it from then on.
The paper_deepread tool
| Argument | Type | Meaning |
|---|---|---|
query |
string, optional | Case-insensitive substring over English/Chinese titles, journals, tags, TL;DR, and full text. Returns up to 20 ranked hits with snippets. |
id |
string, optional | Paper id, report directory name, or 1-based index. Returns one paper. |
With no arguments the tool lists every paper in the bundled library. Each paper carries:
reportHtmlPath— absolute path of the interactive HTML report (read it with local file tools)rawPdfPath— absolute path of the untouched source PDFpreviewPdfPath— absolute path of the figure-cropped report PDFwebUrl— encoded relative URL that resolves under/paper-deepread/
Configuration
The plugin works with no configuration. Optional row config:
- insert:
    - id: paper-deepread
      name: dsh-paper-deepread
      config:
        libraryDir: /absolute/path/to/library   # serve another static-site directory
        skillsDir: /absolute/path/to/skills     # copy the skill elsewhere
        registerSkill: false                    # disable skill install/sync
        skillSync: update                       # update | keep (bundled skill sync)
        siteUrl: http://127.0.0.1:8080          # optional 自动精读 site integration
| Option | Default | Description |
|---|---|---|
dataDir |
$DSH_HOME/paper-deepread |
Managed library, uploads, work directory, state.json, and skill-state.json. |
libraryDir |
unset (use seeded dataDir/library) |
External 文献精读库 root; disables seeding (legacy-compatible). |
skillsDir |
$DSH_HOME/skills (~/.dsh/skills) |
Where the bundled skill is installed/updated. |
registerSkill |
true |
Set false to never install or update the bundled skill. |
skillSync |
update |
update syncs the skill when tracked and unmodified; keep never updates an existing copy. |
siteUrl |
unset (feature off) | Base URL of a running deep-read site, e.g. http://127.0.0.1:8080. Enables the 自动精读 card and the two site proxy routes. |
maxUploadBytes |
83886080 (80 MB) |
Per-upload size limit for the plugin's own inbox. |
Repository layout
DSH-Paper-DeepRead/
├── src/index.js        # host half: Web route + API + tools + skill registration
├── src/manager.js      # managed library, API dispatch, model tools
├── src/store.js        # dataDir, one-time seed, atomic state.json
├── src/uploads.js      # PDF validation + inbox storage
├── src/reports.js      # report scan/hide/delete + library rebuild
├── src/python.js       # skill Python resolution + child processes
├── src/library.js      # library catalogue parser/search (stdlib only)
├── src/skill.js        # skill install + version sync + content hashes (stdlib only)
├── src/site.js         # optional standalone-site health/upload proxy (stdlib only)
├── lib/client.js       # browser half: sidebar icon + main-panel page
├── cordis.patch.yml    # one bundle row: paper-deepread → dsh-paper-deepread
├── skills/paper-deepread-html/   # the bundled deep-read skill
├── library/            # the bundled 文献精读库 static site
├── tests/              # node:test suites (units, API, skill sync, site proxy)
├── assets/icon.svg     # original plugin artwork
├── docs/               # install + architecture notes, screenshots
├── scripts/pack.sh     # syntax check, npm pack, SHA256SUMS
└── dist/               # build output (gitignored)
See docs/architecture.md for the host/client design.
Development
npm run check   # node --check every shipped JavaScript file
npm test        # node:test suites (units, API, skill sync, site proxy)
npm run pack    # dist/dsh-paper-deepread-1.5.2.tgz + dist/SHA256SUMS
The package is published as a GitHub release tarball; it is not required to be on npm.
Known limitations
- The first ingest/report build prepares a PyMuPDF interpreter through the bundled
skill's
setup_env.sh(cached venv under~/.cache/paper-deepread; the first run may download PyMuPDF). Rebuilding the library index does not need PyMuPDF: without a prepared interpreter it falls back to a plainpython3 --no-thumbsrebuild. - The plugin never calls a model itself: upload -> deep-read stays agent-driven through
paper_deepread_uploads/paper_deepread_reports. The 自动精读 card is the exception only in the sense that it hands the PDF to a site worker; the plugin still runs no model. - Skill sync only updates copies it installed itself (tracked by a content hash). A skill directory that already existed before v1.2.0 is treated as user-managed and kept with a warning; delete it once to let the plugin manage it.
- The 自动精读 card needs the standalone site to be running and reachable from the Harness host. The site API stays same-origin-only; all browser traffic goes through the plugin proxy on the Harness origin.
library/index.htmlprobes/api/libraryfor live updates; that endpoint does not exist in the plugin route, so the page shows its embedded catalogue as an offline snapshot. Navigation, reports, and PDFs are unaffected.- The browser panel is loaded through dsh's client module system; the host and client halves activate only in a Web profile.
Uninstall
dsh plugin --profile web remove dsh-paper-deepread
Restart dsh web. The copied skill under ~/.dsh/skills/paper-deepread-html is left in
place (delete it manually if you do not want to keep it); old copies backed up by the
version sync stay under ~/.dsh/skills/.backup/. The managed data directory
(~/.dsh/paper-deepread, including skill-state.json) is not removed automatically.
License
MIT © 2026 HaoKuo
Repository: https://github.com/HaoKuo/DSH-Paper-DeepRead
No comments yet. Be the first to write one.